50.1k


TL;DR
Real-time performance per dollar depends on both the cost of keeping incoming data query-ready and how much work that preparation leaves for the query engine.
- CostBench measures both effects as one continuous workload under sustained load: fresh rows are ingested and made query-ready while aggregate and drill-down queries continue to run.
- We tested ClickHouse Cloud, Snowflake, BigQuery, and Redshift Serverless using each vendor’s recommended real-time ingest path, streaming more than 100 billion stock-market quotes at a target rate of 1 million rows per second.
- ClickHouse Cloud had the lowest fresh-data-path cost, query-serving cost, and accumulated runtime. The tested alternatives delivered 412–1,996× worse end-to-end performance per dollar.
- This post launches a series of 1:1 analyses tracing the architectures and billing behind those results.
The path from fresh data to fast queries shapes performance per dollar
A real-time analytics system serves queries over a dataset that is constantly changing. New rows keep arriving while users, applications, and agents query data that may already span billions or trillions of rows. Each new row must become query-ready while those queries continue to run.
CostBench measures the end-to-end performance and cost of real-time analytics across cloud data warehouses. Its first results show that query engines are only part of what separates these systems:
Systems vary dramatically in the cost and efficiency of carrying incoming data from arrival to query readiness.
Under sustained load, that work can shape performance per dollar as much as query execution itself: it carries its own direct cost, and the state it produces determines how much work remains for the query engine.
This first end-to-end round tested ClickHouse Cloud, Snowflake, BigQuery, and Redshift Serverless using push-based ingestion.
CostBench measured ingestion, ongoing query-readiness work, and aggregate and drill-down query serving - all running together. This post first explains what query-ready means, then shows how the benchmark works, and presents the overall results. The 1:1 posts that follow trace those results through each provider’s architecture and billing model.
What makes data query-ready
Consider a common analytical question about stock quotes: How many AAPL quote updates arrived each day?
The query filters for AAPL, groups its quotes by day, and counts the rows in each group:
SELECT
    Day,
    COUNT(*) AS quotes
FROM quotes
WHERE Symbol = 'AAPL'
GROUP BY Day;This is exactly the kind of query analytical systems are built to run fast.
Query-ready data is organized and prepared so the query engine reads less data and does less work at query time.
For our “AAPL a day” query, three steps help the engine read less data and do less work.
Store data by column
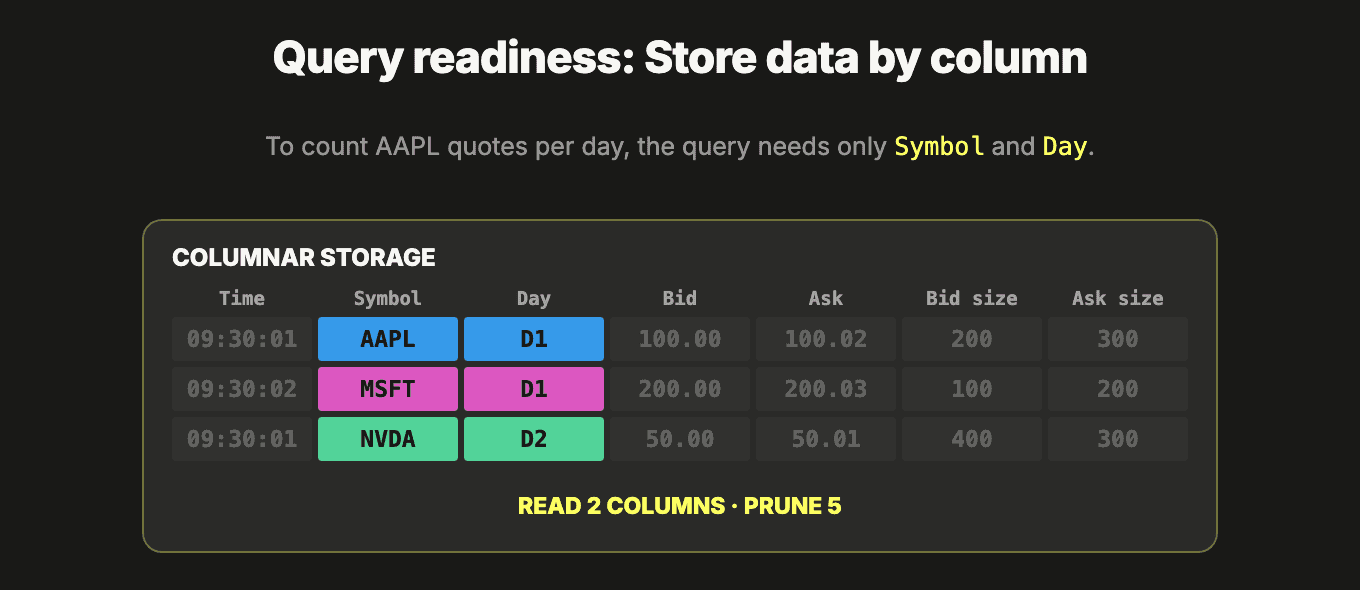
Our query needs Symbol to find AAPL’s quotes and Day to group them. It does not need any other column.
Columnar storage lets the engine read only those two columns and skip the rest. In the example below, that means reading 2 columns instead of 7.
Columnar layouts also help the engine process the data it reads. With a column’s values together in memory, the engine can apply an operation to a batch of values in a simple loop. This vectorized execution reduces the overhead of handling rows individually. Suitable operations can also use SIMD instructions, which process several values with one instruction.
Organize data for chunk pruning
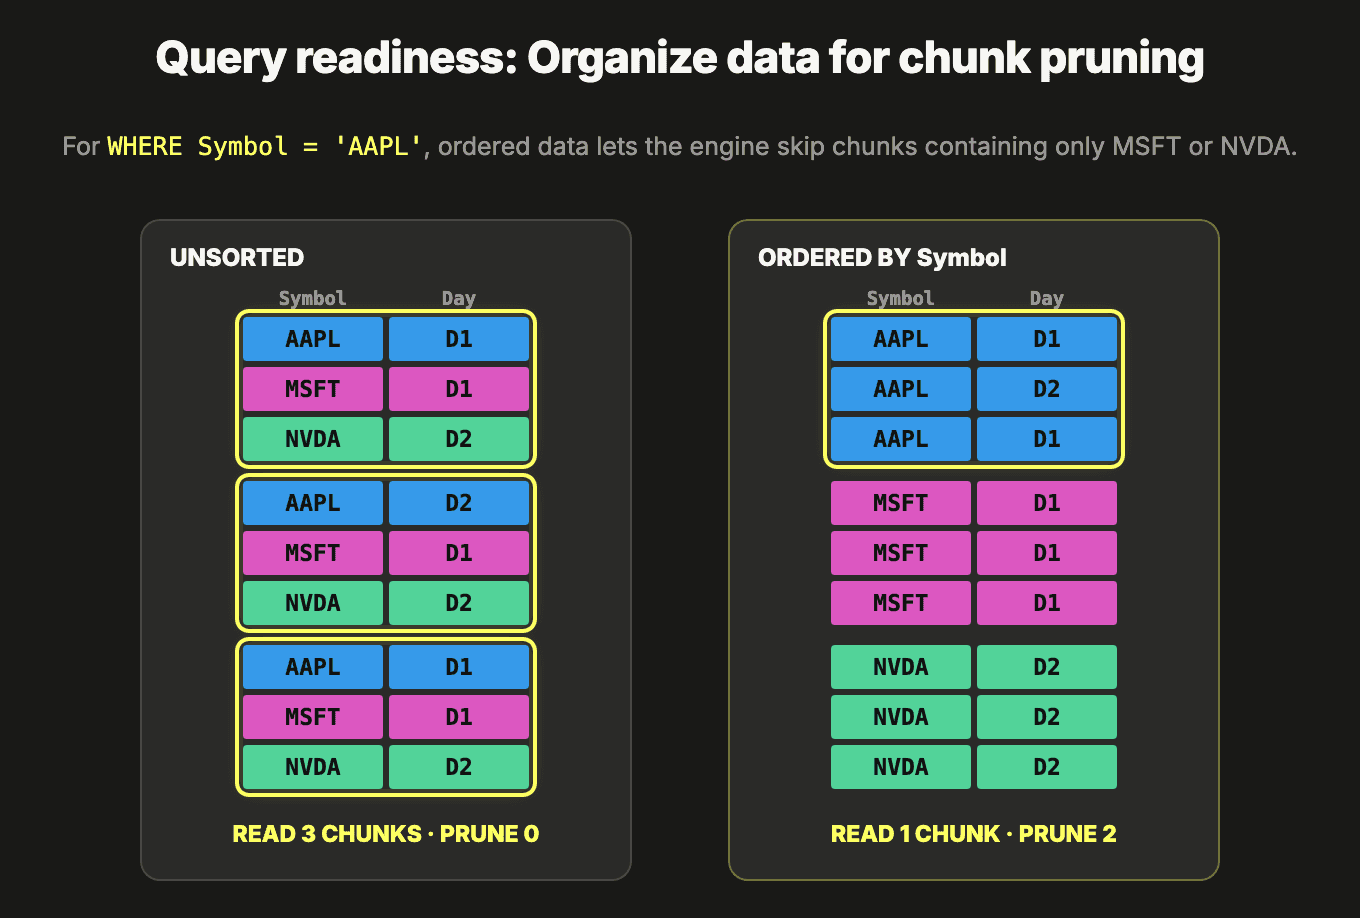
The batches described above are chunks of consecutive column values. Before reading a chunk of stored data, the engine checks its metadata and skips it when the metadata shows it cannot contain values matching the query’s filter. This is chunk pruning.
Our query already reads only Symbol and Day columns. But in the unsorted example, AAPL quotes appear in all three chunks, so the engine must read all three.
Sorting by Symbol keeps each stock’s quotes together. For WHERE Symbol = 'AAPL', the engine now reads one AAPL chunk and skips the MSFT and NVDA chunks. That leaves three AAPL quotes to group by day and count.
Pre-aggregate to reduce query-time work
At billions or trillions of rows, scanning and aggregating raw data can be too slow for interactive analytics. When those queries run repeatedly, as they often do in dashboards, the compute cost can also add up.
Pre-aggregations move that work out of each query and into data preparation. They maintain a much smaller set of summary rows, reducing both the data read and the grouping and aggregation performed at query time. The summaries retain the grouping dimensions and aggregate results the queries need, allowing the engine to combine prepared results instead of calculating them from individual rows.
In our example, pruning leaves three AAPL quotes to group by day and count. Pre-aggregation prepares those counts in advance: it groups quotes by Symbol and Day and calculates COUNT(*) for each group. This turns nine quotes into four summary rows, each containing a count for one stock on one day.
Because queries may still filter the summary rows, pre-aggregated data also benefits from a pruning-friendly physical layout. Our summary rows are ordered by Symbol. For WHERE Symbol = 'AAPL', the engine reads only the two AAPL summary rows and skips the MSFT and NVDA rows. Those two rows already contain the daily counts - two quotes on D1 and one on D2 - so the engine no longer needs to group and count the individual AAPL quotes on every execution.
For time-sensitive use cases such as monitoring market activity, these summaries must stay current with the underlying quotes, ideally updating as new quotes become queryable.
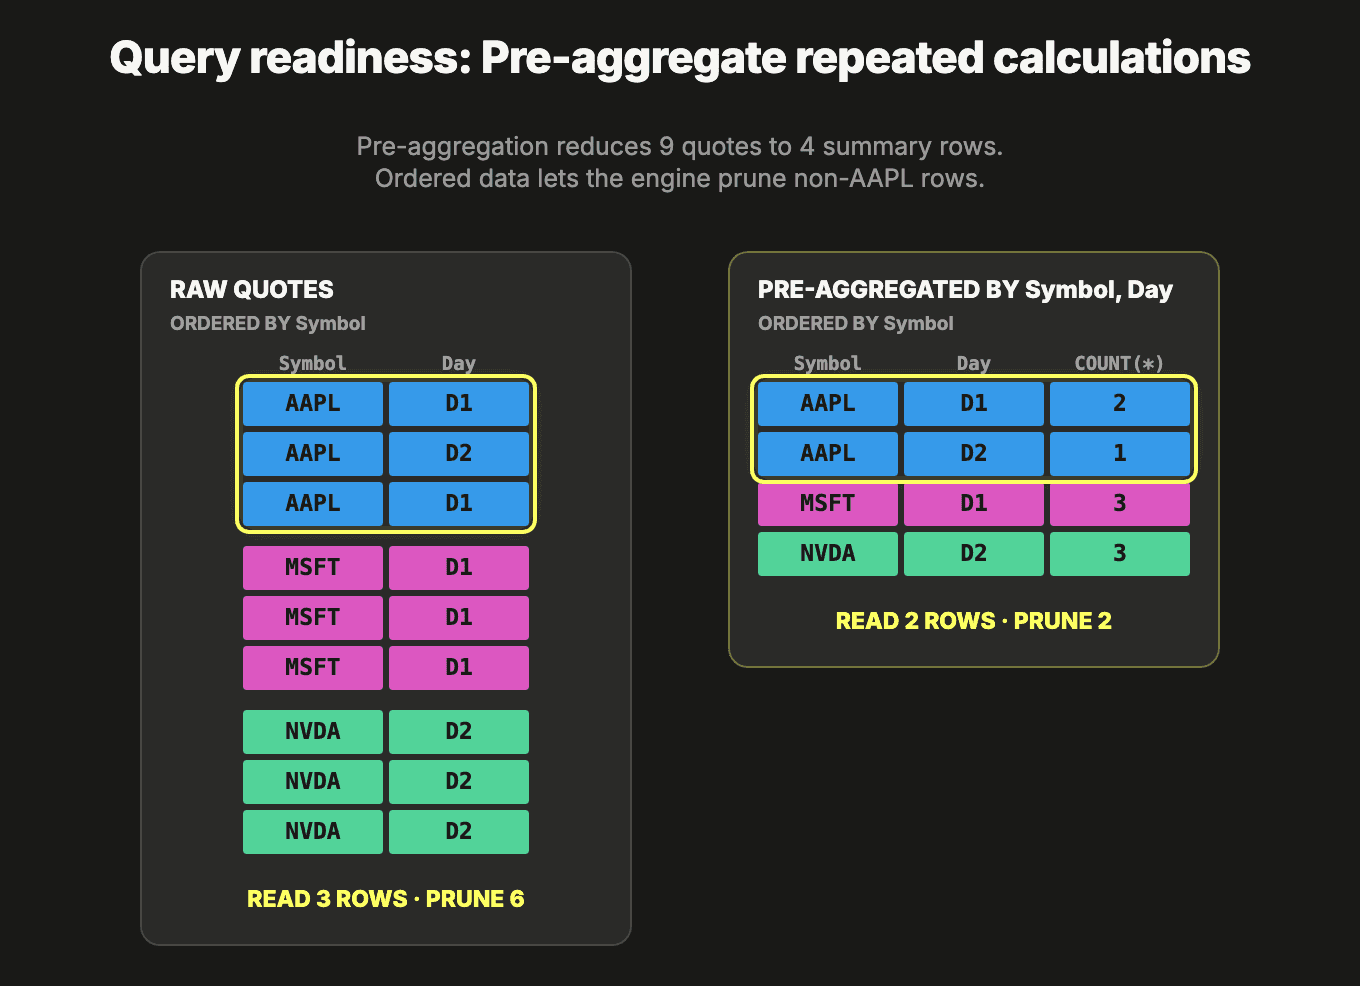
For our AAPL query, columnar storage lets the engine skip unused fields, sorting by Symbol lets it skip unrelated stocks, and current pre-aggregations let it skip grouping and counting individual quotes. Together, these preparations make data query-ready for analytical queries like this one: the query engine reads less data and performs fewer calculations.
Up to 1,996× better real-time performance per dollar
That’s what ClickHouse Cloud delivered in CostBench under continuous load. See what it can do for your data - sign up today.
Try ClickHouse CloudReal-time systems must make fresh data query-ready as it arrives
With a fixed dataset, that preparation can happen before queries begin. In a real-time system, new rows arrive continuously while queries keep running.
“A real-time system should have access to real-time data so it's viable for making real-time decisions based on the freshest data.” — Instacart Engineering
We call the continuous work that carries each new row from arrival to query readiness the fresh-data path. It comprises three responsibilities that must remain active in parallel:
① Ingest fresh data into columnar storage as it arrives.
② Maintain pruning-friendly physical layouts for event-level and pre-aggregated data through sorting, clustering, partitioning, or equivalent structures.
③ Maintain current pre-aggregations as new data arrives, keeping common grouping and aggregation work out of query time.
These are logical responsibilities, not a strict execution sequence. A system may fuse them in a single write path - for example, sorting incoming rows, computing pre-aggregations, and sorting those results before either representation is written to storage. Other systems complete some of this work asynchronously after ingestion.
Indexes, metadata, compaction, and other provider-specific structures also affect the cost and efficiency of this work.
Alongside the fresh-data path, the query engine serves two typical analytical paths. Both depend on the preparation described above:
-
Pre-aggregated path: Interactive aggregate queries depend on ③ to keep repeated grouping and aggregation out of query time. If they filter the summarized rows, they also depend on ② to prune irrelevant chunks.
-
Event-level path: Selective drill-down queries read event-level data directly and therefore depend on ② to avoid scanning most of the data. Even when these queries take seconds, pruning is what makes them feasible at scale; they may still group or aggregate the remaining rows.
An efficient fresh-data path lowers its own cost - and the work left for queries
A system can sustain ingestion while its query readiness falls behind.
Keeping up with incoming data does not guarantee that the system is keeping up with everything needed to query it efficiently.
That gap can affect answer freshness: new stock quotes may be ingested promptly, yet a risk query can still return results based on an outdated view of the market.
It can also affect query efficiency, even when queries can see the latest data. If ordering or pre-aggregation falls behind, the query engine may need to scan more data, reconcile newer rows, or repeat grouping and aggregation at query time.
The interactive diagram below shows this second effect while data keeps flowing. Watch the loop or drag the slider to see how the query engine’s scanning and aggregation work shrinks as ordering and pre-aggregation catch up - and grows when preparation falls behind.
That extra query work consumes read-side compute and increases latency and query-serving cost. An efficient fresh-data path therefore pays off in two places: the cost of preparing data and the runtime and cost of the queries it serves.
CostBench measures both effects together
CostBench follows the same continuously growing dataset from ingestion through row visibility, event-level layout maintenance, and pre-aggregation freshness, while aggregate and drill-down queries run on a fixed schedule. The query definitions stay fixed, but their answers must continually account for newly arriving data. This makes both sides visible: the direct cost of keeping data query-ready and the performance and cost of serving queries from the state the system actually achieved.
The first results show that some systems sustained ingestion while pre-aggregation lag accumulated or query latency rose - moving more work onto the read path and driving up query-serving cost.
How CostBench keeps the comparison fair
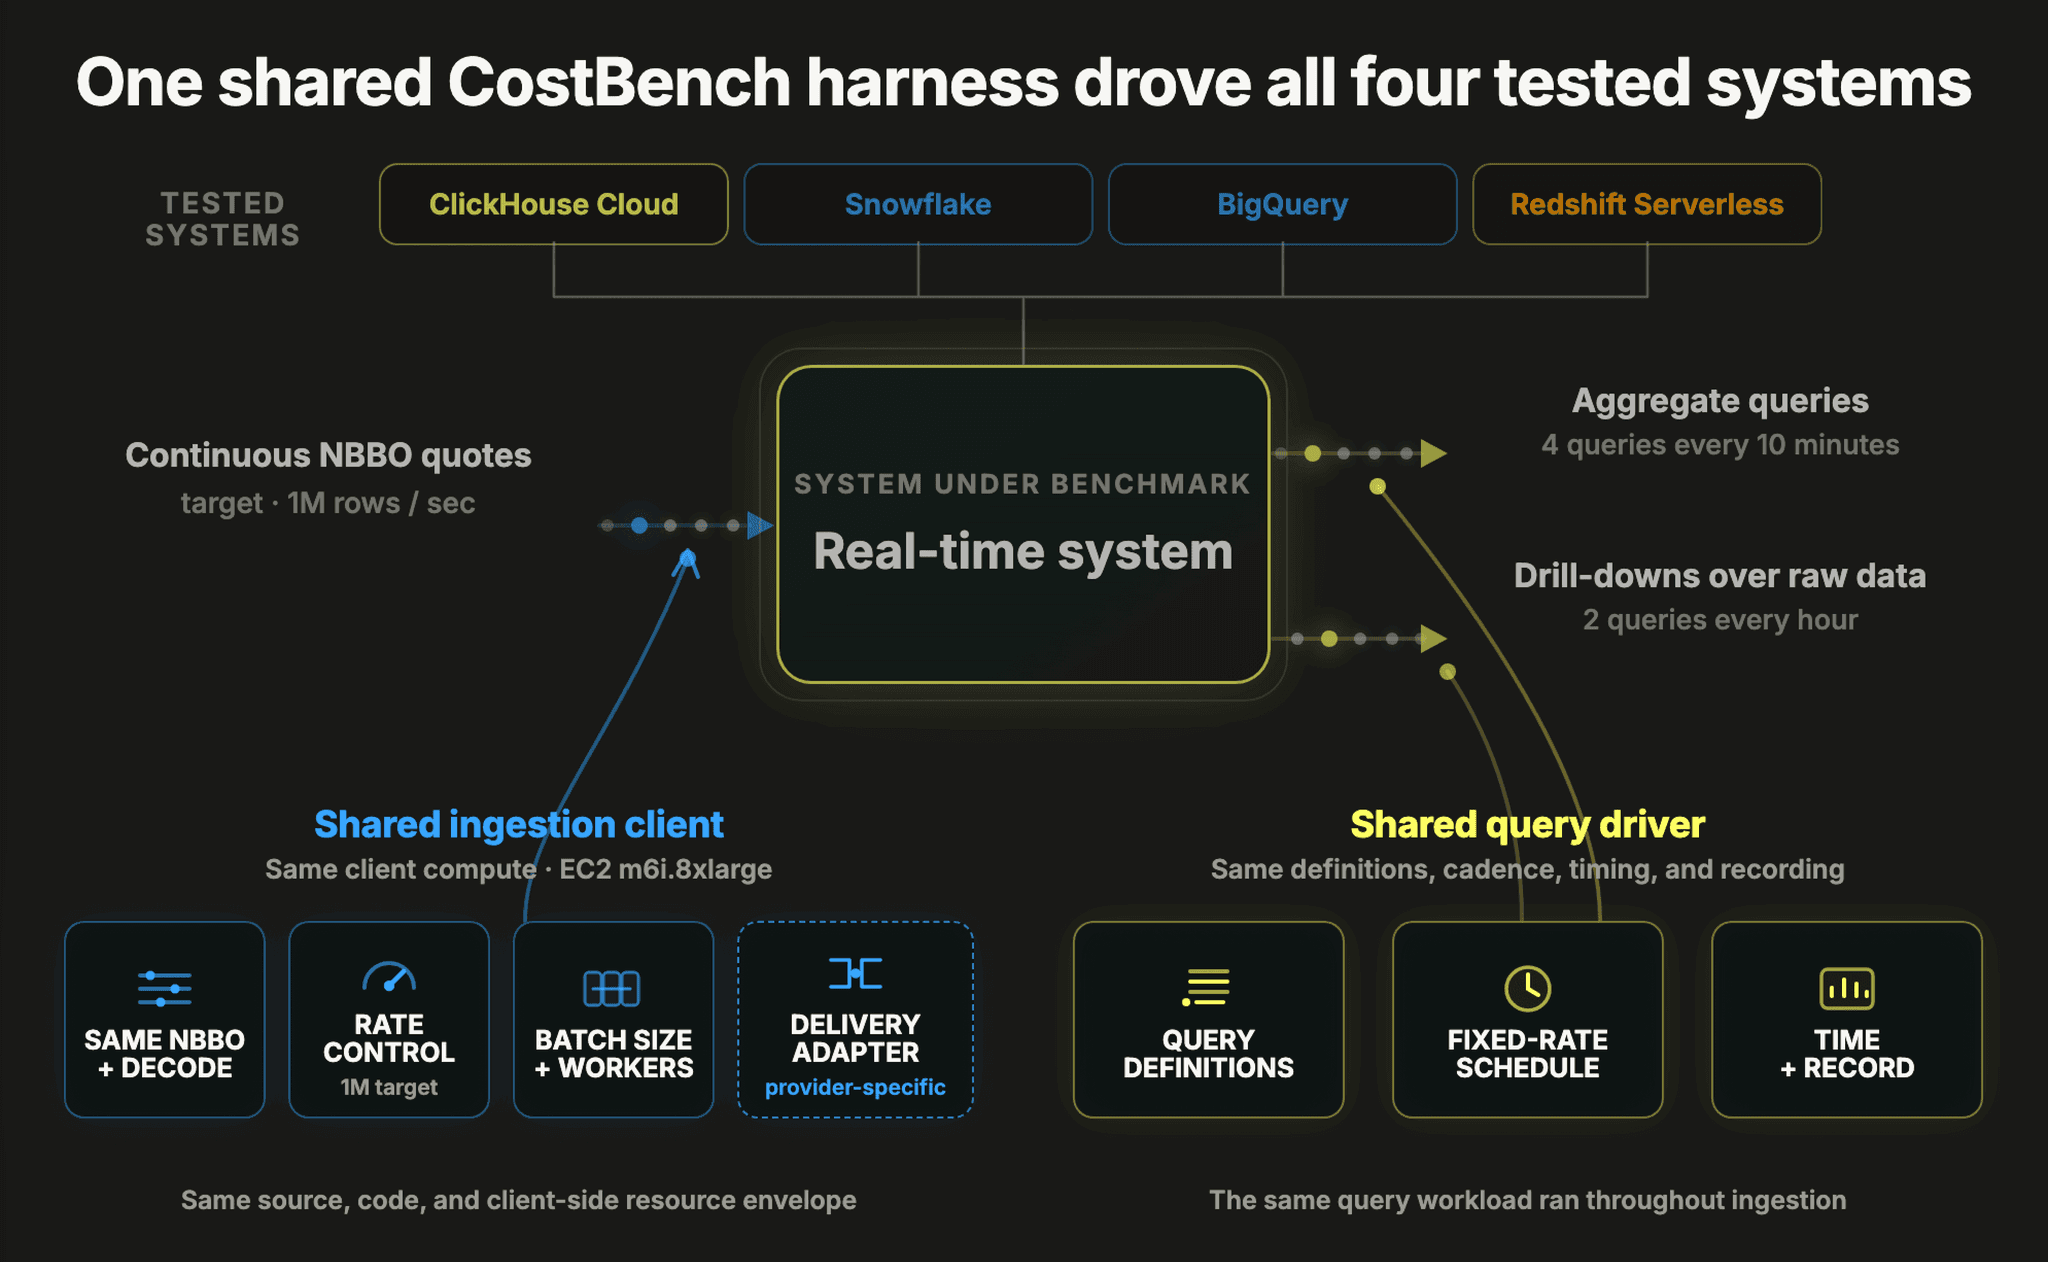
This round used push-based ingestion across ClickHouse Cloud, Snowflake, BigQuery, and Redshift Serverless: one shared client sent the stream directly through each system’s recommended low-latency ingest path. Four controls kept the comparison like-for-like while respecting each system’s architecture:
-
Same workload: Each system received the same 113.2-billion-row National Best Bid and Offer (NBBO) stock-market quotes dataset, schema, layout intent, target ingestion rate of 1 million rows per second, queries, and cadence.
-
Comparable resources: We aligned read-side compute where a meaningful comparison was possible and used the smallest tested configurable fresh-data-path compute that sustained the target during calibration.
-
Complete platform paths: Each system used its recommended real-time architecture with a low latency push-based ingestion path. Managed and serverless services retained their native scaling, and their metered work remained in the benchmark’s cost.
-
One shared harness: The same source files, decoding logic, client host, rate controller, scheduler, timing, and recording logic drove every system; only the destination adapter changed.
We configured matching sorting or clustering keys across systems for both raw data and daily pre-aggregations. These layouts support the workload’s stock-symbol filters. The pre-aggregations group quotes by stock symbol and day, maintaining the counts, sums, and price minima and maxima that the aggregate queries use. Each system therefore had to keep the same preparation current for the same query workload as new rows arrived.
Later rounds may also test pull-based variants using one shared external stream, to give a more complete picture of real-time performance per dollar.
The shared harness holds the workload constant. CostBench measures how each system handles it.
BENCHMARK METHODOLOGY AND FAIRNESS CONTROLS (click to expand)
INGESTION MODEL
The client read NBBO data from Parquet files, decoded it into raw rows, and pushed the stream directly into each platform’s target tables through its vendor-recommended low-latency real-time ingest path. Later rounds will test pull-based variants using one shared external stream.
WORKLOAD MODEL
In a real-time analytics system, new events are generated continuously at the source at an application-driven rate. Future rows do not yet exist, so the database is never handed a complete backlog to load as quickly as possible. CostBench reproduces that operating condition by using the Parquet files as a deterministic source, decoding their rows, and releasing them as a paced continuous stream while each platform keeps the arriving data query-ready and serves scheduled queries.
DATASET AND ACTIVE WINDOW
Every system received the same complete 113.2-billion-row dataset of narrow, 12-column National Best Bid and Offer (NBBO) stock-market quotes.
All systems used the following sorting or clustering keys:
-
Event-level data:
(sym, t)— stock symbol and event timestamp. -
Daily pre-aggregations:
(sym, day)— stock symbol and day.
The harness replayed the entire source as one uninterrupted stream toward a target rate of 1 million rows per second and continued until the final source row had been ingested. At exactly the target rate, that active-ingestion window would last about 31.4 hours; observed durations varied by system.
SHARED INGESTION CLIENT
The same source files, schema, row-decoding logic, and workload-generation code drove ClickHouse Cloud, Snowflake, BigQuery, and Redshift Serverless. For every system, the client ran on the same AWS EC2 m6i.8xlarge instance, used the same rate controller, and adjusted batch size and worker parallelism to pace the destination toward the target.
BEST-PRACTICE PLATFORM CONFIGURATION
Only the destination-specific delivery adapter changed. Inside each platform, we used its vendor-recommended low-latency push-based real-time ingest path and documented best practices for keeping incoming data query-ready. Differences between those paths are part of the benchmark.
RESOURCE-SIZING POLICY
We aligned read-side compute by estimated CPU capacity wherever the platforms allowed a meaningful comparison. For configurable fresh-data-path compute, we used the smallest tested configuration that sustained the target rate of 1 million rows per second during calibration while keeping incoming data query-ready. Managed and serverless components used their native scaling, and their metered work remained part of the benchmark’s cost. Observed end-to-end throughput is reported separately from the configured target.
SHARED QUERY DRIVER
From the beginning of ingestion through the final source row, the same four interactive aggregate queries ran every 10 minutes and the same two selective drill-down queries every hour, using identical fixed-rate scheduling, timing, and result-recording logic.
QUERY WORKLOAD
The workload is deliberately designed to stress test the efficiency of the fresh-data path: queries run throughout ingestion, and their answers must account for newly arriving data rather than a fixed historical slice. Each system must therefore keep preparing fresh data for those queries while continuing to serve them.
The query labels describe the data path, not whether the SQL itself contains aggregation: aggregate queries read maintained pre-aggregations; drill-down queries calculate directly from event-level rows.
How fresh arrivals enter the queries
All six queries cover the history ingested so far, without a date or time cutoff:
- Queries filtered by symbol (A1, A2, D1, D2): The selected symbols stay the same, but their matching data keeps growing as more quotes arrive. For example, sym = 'AAPL' includes newly ingested Apple quotes alongside its earlier quotes. The eight-symbol watchlist works the same way.
- Queries without symbol filters (A3, A4): These cover all symbols through the maintained daily pre-aggregations. Newly ingested quotes contribute to the summaries queried for historical price ranges and daily market activity.
For aggregate queries, those incoming quotes must be incorporated into the pre-aggregations. For drill-down queries, the new event-level rows must be available in a layout that supports efficient filtering.
What each query does
Interactive aggregate queries (A1–A4) read the continuously maintained daily pre-aggregation. A1 returns an all-time summary for one symbol; A2 summarizes an eight-symbol watchlist; A3 finds the largest historical price ranges by symbol; and A4 returns market-wide activity by day. A1 and A2 use the leading sym layout key, while A3 and A4 read the complete rollup.
Selective drill-down queries (D1–D2) read event-level data directly for one symbol across its complete history. D1 builds hourly OHLCV bars with VWAP, volatility, spread, and quote count. D2 returns a single-row risk-and-liquidity profile covering mid-price volatility, spread distribution and tail percentiles, order-book imbalance, and spread-versus-depth correlation.
How preparation matches the queries
The workload exercises both forms of preparation. D1/D2 filter the raw data by sym, the leading column of (sym, t). A1/A2 filter the daily summaries by that same leading column in (sym, day); A3/A4 read summaries across all symbols.
The daily pre-aggregation groups by (sym, day) and maintains the counts, sums, minima, and maxima used by A1–A4. For example, total quotes comes from summing prepared quote counts, while average spread comes from dividing the accumulated spread sum by the accumulated quote count.
CACHE POLICY
Query-result caching was disabled on every system so measured runtimes reflect query execution rather than retrieval of a previously computed answer. This also matches the workload’s freshness requirement: newly arriving data must contribute to the answers, so an earlier cached result may no longer be current.
Ordinary underlying data caches were allowed to remain warm, reflecting continuous operation. These caches can reduce the cost of reading data, but they do not replace query execution: the engine must still account for new arrivals and perform the filtering, reconciliation, or aggregation required by each query.
The full benchmark definition, accepted runs, results, cost summaries, and reproduction steps are open in the CostBench repository.
Databricks Lakehouse/RT remains in beta, so it is outside this first comparison and will be tested after general availability.
Fast answers while fresh data keeps arriving
First, look at what the systems delivered while ingestion and queries ran together. The chart below adds up the time spent answering the measured aggregate and drill-down queries as the dataset grows.
ClickHouse Cloud accumulated the least query runtime under continuous ingestion.
ClickHouse Cloud is purpose-built end to end for fast answers on continuously fresh data. Its advantage comes from how the complete system works together - from preparing each incoming row to serving current answers.
Serving those queries quickly is one part of the result. What did it cost to keep incoming data query-ready and serve that workload? CostBench brings those dimensions together.
CostBench ranks systems by real-time performance per dollar
Cloud platforms pair fundamentally different billing models with often radically different fresh-data paths and query engines. To compare cost and performance across them, CostBench combines three inputs into one lower-is-better score:
① Fresh-data-path cost: Complete-ingest cost for continuous ingestion, event-level layout maintenance, and pre-aggregation.
② Normalized query-serving cost: Cost of executing the same scheduled queries at each system’s applicable read-side rate.
③ Total query runtime: Accumulated end-to-end runtime for that query workload during active ingestion.
The score rewards systems that keep incoming data query-ready economically and serve the workload quickly. Lower is better.
Database storage costs are excluded from the score because their impact is small over the benchmark’s duration; see the calculation note below.
SCORE CALCULATION AND METERING NORMALIZATION (click to expand)
WHAT THE FULL-PATH SCORE MEANS
The score answers one question:
Where do you get the most full-path real-time performance per dollar spent?
It combines the cost of keeping continuously arriving data query-ready with the cost and total runtime of serving the same query schedule. A lower score means a better combination of lower end-to-end cost and faster query serving under continuous ingestion.
CALCULATION
End-to-end score = (fresh-data-path cost + normalized query-serving cost) × total query runtime. Lower is better.
FRESH-DATA-PATH COST
The fresh-data-path component uses the complete-ingest cost of accepting the full 113.2-billion-row stream and keeping event-level and pre-aggregated data query-ready. Configured compute is priced for its observed active duration; managed and serverless services use their metered work.
NORMALIZED QUERY-SERVING COST
We normalize query cost as accumulated end-to-end runtime × read-side compute price, as if compute were billed per second. This compares how much query work each system completes for the same amount of paid compute time. Per-second normalization removes differences in idle timeouts and minimum billing windows.
For this benchmark, we apply that calculation to equal numbers of query executions while ingestion is running, matched by dataset progress. Each execution’s full end-to-end runtime is multiplied by the applicable read-side compute rate, and the costs are summed. The result is a normalized comparison cost rather than a reconstruction of actual bills.
WHAT ABOUT STORAGE COSTS?
Database storage is excluded from the score. Earlier CostBench experiments with approximately 113.2 billion rows illustrate its limited impact over a short ingest run: the measured raw-table and pre-aggregation footprints corresponded to approximately $9.83 per month for ClickHouse Cloud and $16.07 for Snowflake, using the benchmark’s recorded ClickHouse and Snowflake storage rates.
Charging those complete footprints for an entire 37-hour run would add approximately $0.50 and $0.81, respectively, using a 730-hour month. This deliberately charges the final footprint throughout, even though the dataset grows during ingestion. For context, the current comparison’s fresh-data-path costs are $28.69 and $79.42, respectively. These storage estimates illustrate scale; they are not measured storage bills for the current runs. Current cost results.
Storage costs become more important over longer retention periods. This exclusion concerns database storage; required ingestion infrastructure, including Redshift’s MSK broker storage, remains included in the fresh-data-path cost.
BOUNDARY AND EXCLUSIONS
Fresh-data-path cost covers the complete 113.2-billion-row ingest. Query-serving cost and total runtime cover matched, accepted queries during active ingestion. Storage, free tiers, discounts, idle capacity, minimum billing, post-ingestion queries, failed attempts, and standing fallback capacity are excluded. Provider-specific fallback allocations in the accepted query-cost model remain included.
RANKING
The system with the lowest absolute score becomes the 1× baseline. Every other system is reported as N× worse.
RELATED METHODOLOGY
This extends CostBench’s earlier metering-granularity and ranking methodology from query-side tests to the complete fresh-data path.
The fresh-data path widens the performance-per-dollar gap
We began with a thesis:
Under sustained load, keeping data query-ready can shape performance per dollar as much as query execution itself.
The results now show just how large that impact can be.
Query-side only: a 32–101× gap
The earlier query-side comparison measured already-loaded, query-ready data, isolating query-serving cost and runtime.
Within that boundary, Snowflake, Redshift Serverless, and BigQuery Capacity delivered 32× to 101× worse query-side cost-performance than ClickHouse.
With the fresh-data path: a 412–1,996× gap
The end-to-end comparison adds the continuous cost of ingesting new rows and maintaining their query-ready state. The benchmark adds that cost to normalized query-serving cost and combines the total with accumulated query runtime during active ingestion.
The result closes the loop:
Once the fresh-data path is included, the performance-per-dollar gap expands from 32–101× on the isolated query side to 412–1,996× end to end.
The final animation separates the two dimensions behind that wider score: end-to-end cost and accumulated query runtime.
The final comparison brings the runtime advantage into its full cost context. ClickHouse Cloud combined the lowest accumulated query runtime with the lowest fresh-data-path and normalized query-serving costs in this benchmark.
-
Fresh-data path: As the 1:1 analyses will show, ClickHouse Cloud had the lowest-cost fresh-data path and was the only tested system that kept both its event-level and pre-aggregated data current as ingestion continued.
-
Query serving: Because it completed that work as rows arrived, its query engine had less filtering, grouping, and aggregation work left to do - resulting in the lowest accumulated query runtime and the lowest normalized query-serving cost.
ClickHouse Cloud’s advantage compounded: the lowest-cost fresh-data path kept data query-ready as it arrived, leaving less work - and therefore less runtime and cost - for the measured query workload.
The CostBench end-to-end real-time path series continues with 1:1 analyses of each provider’s architecture and billing model, tracing where query-readiness work happens, where it falls behind, and how those choices shape performance per dollar.