5.1만

ClickHouse is a common home for time-series data, from logs and infrastructure metrics to sales and customer activity. Our own internal logging platform, LogHouse, stores more than a quadrillion time series rows. Forecasting future values and detecting unusual observations are common tasks for this data, but training and maintaining a separate classical time series model, like ARIMA, for every service, customer, or product can be difficult as the number of series grows.
Time-series foundation models (TSFMs) promise to remove that per-series training requirement: pretrained on many series, they can produce zero-shot forecasts from a new series' history, which can also be used to flag observations that deviate from expectations. This makes them a natural fit for ClickHouse's real-time analytics and data warehousing workloads, where SQL already handles the aggregation, time bucketing, and filtering needed to construct each series.
In this post, we connect TimesFM 3.0 to ClickHouse through executable user-defined functions. As an illustration, we use recorded retail sales from the M5 dataset to forecast daily demand and identify unusual historical observations.
Setup
The companion clickhouse-timeseries-ai repository contains a TimesFM model server, ClickHouse executable UDF definitions, and a Docker Compose configuration. You need Git, Docker with Compose v2, and internet access for the first build and model download. Allow roughly 8 GB of available memory and several GB of disk space as a starting point; this is not a measured minimum. No GPU is required.
Clone the repository and start the demo:
git clone https://github.com/ClickHouse/clickhouse-timeseries-ai.git
cd clickhouse-timeseries-ai
docker compose up --build -d --wait --wait-timeout 1200This starts ClickHouse and the model server, downloads a pinned checkpoint, and registers the functions. The default configuration uses CPU inference and caches the weights for subsequent starts.
TimesFM inference runs outside the ClickHouse process. An executable Python UDF receives a numerical array, sends it to the model service over HTTP, and converts the response into ClickHouse arrays and tuples. The service exposes two endpoints:
/v1/timeseries/forecast
/v1/timeseries/anomaliesForecasting essentially wraps timesfm3.TimesFM3Evaluator.predict_batch. No training or fine-tuning is performed for the examples below.
The downloaded TimesFM 3.0 weights have non-commercial, non-production restrictions. Check the applicable model terms before using this setup beyond a local evaluation. These functions are part of the demo, not built-in ClickHouse AI functions (yet!).
SQL interface
The functions operate on complete series:
aiForecast(values, horizon)
aiForecastMultivariate(targets, horizon, past_covariates, future_covariates)
aiDetectAnomalies(values, options_json)values is an Array(Float64). Inputs do not need to be literal arrays or stored array columns: they can be SQL expressions built from CTEs, subqueries, joins, or aggregated query results. For example, a query can filter and aggregate events into daily totals, collect those totals into a time-ordered array, and pass it directly to aiForecast. The functions receive the resulting arrays, not a table or query string.
Forecasts return an array of named tuples (expected, lower_bound, upper_bound, quantiles), one per future step. expected is the median; the lower and upper bounds are q10 and q90, forming a nominal 80% prediction interval. quantiles contains all nine native TimesFM quantiles, q10 through q90, as (level, value) pairs. All values come from the same model call.
The SQL helper aiForecastQuantile(prediction, 0.8) selects q80 from a forecast step, for example, to use a higher demand estimate in inventory planning. aiForecastInterval(prediction, 0.6) returns the q20–q80 bounds for a nominal 60% interval. These helpers only select values from the returned tuple; they do not invoke the model. Unsupported quantiles or intervals, including a 95% interval from this checkpoint, raise an error rather than extrapolating beyond its output.
Multivariate inputs are Array(Array(Float64)), with one inner array for each target series or additional input feature. A target series is a sequence of values to predict, such as daily sales. An input feature provides context, such as a promotion schedule or event-day indicator. Historical channels are aligned by time. Known-future covariates must also cover the forecast horizon. The result contains one forecast array per target. This can represent related demand series together with a promotion calendar, for example.
aiDetectAnomalies accepts optional past_covariates and future_covariates arrays in its options_json, with one inner array per feature. All inputs cover the same observed dates; the service supplies each known-future channel through the end of each scored window, but target values only through its forecast origin. The output remains one aligned array. This is quite dense - a full example follows in the daily sales forecast section below where future_covariates looks like [0,0,0…1,0…] indicating known future events, a Christmas holiday in this case.
The model receives ordered numbers, not timestamps or table names. SQL determines the aggregation and sampling interval, handles missing periods, and orders each series. A horizon of 28 therefore means 28 days for daily input, or 28 hours for hourly input. Neither the UDF nor the model infers the time grid from the source table.
Forecasting daily sales
M5 contains daily unit sales for products sold in ten Walmart stores spanning 5 years: 2011-01-29 through 2016-04-24. It’s possible M5 is included in the model training, but our goal here is to demonstrate how to use a time series model, not to prove effectiveness. For this example, m5.store_daily contains daily totals of the products represented in the dataset, with columns store_id, day, and units:
store_id | date | units | |
|---|---|---|---|
1 | WI_1 | 2016-04-24 | 4874 |
2 | CA_1 | 2016-04-24 | 6113 |
3 | CA_2 | 2016-04-24 | 6082 |
7 | TX_1 | 2016-04-24 | 4033 |
The following query uses 730 days of observations through March 27, 2016, to forecast the next 28 days for each store:
SELECT
store_id,
aiForecast(
arrayMap(p -> p.2, arraySort(p -> p.1, groupArray((day, units)))),
toUInt32(28)
) AS forecast
FROM m5.store_daily
WHERE day >= toDate('2014-03-29') AND day < toDate('2016-03-28')
GROUP BY store_id
ORDER BY store_id
SETTINGS max_threads = 1;groupArray collects the observations for each store. Sorting the (day, units) tuples makes their order explicit before arrayMap extracts the values. Each store produces one model request and receives 28 forecast tuples, corresponding to March 28 through April 24. max_threads = 1 limits query parallelism for this demo's model server, which accepts one active inference request at a time.
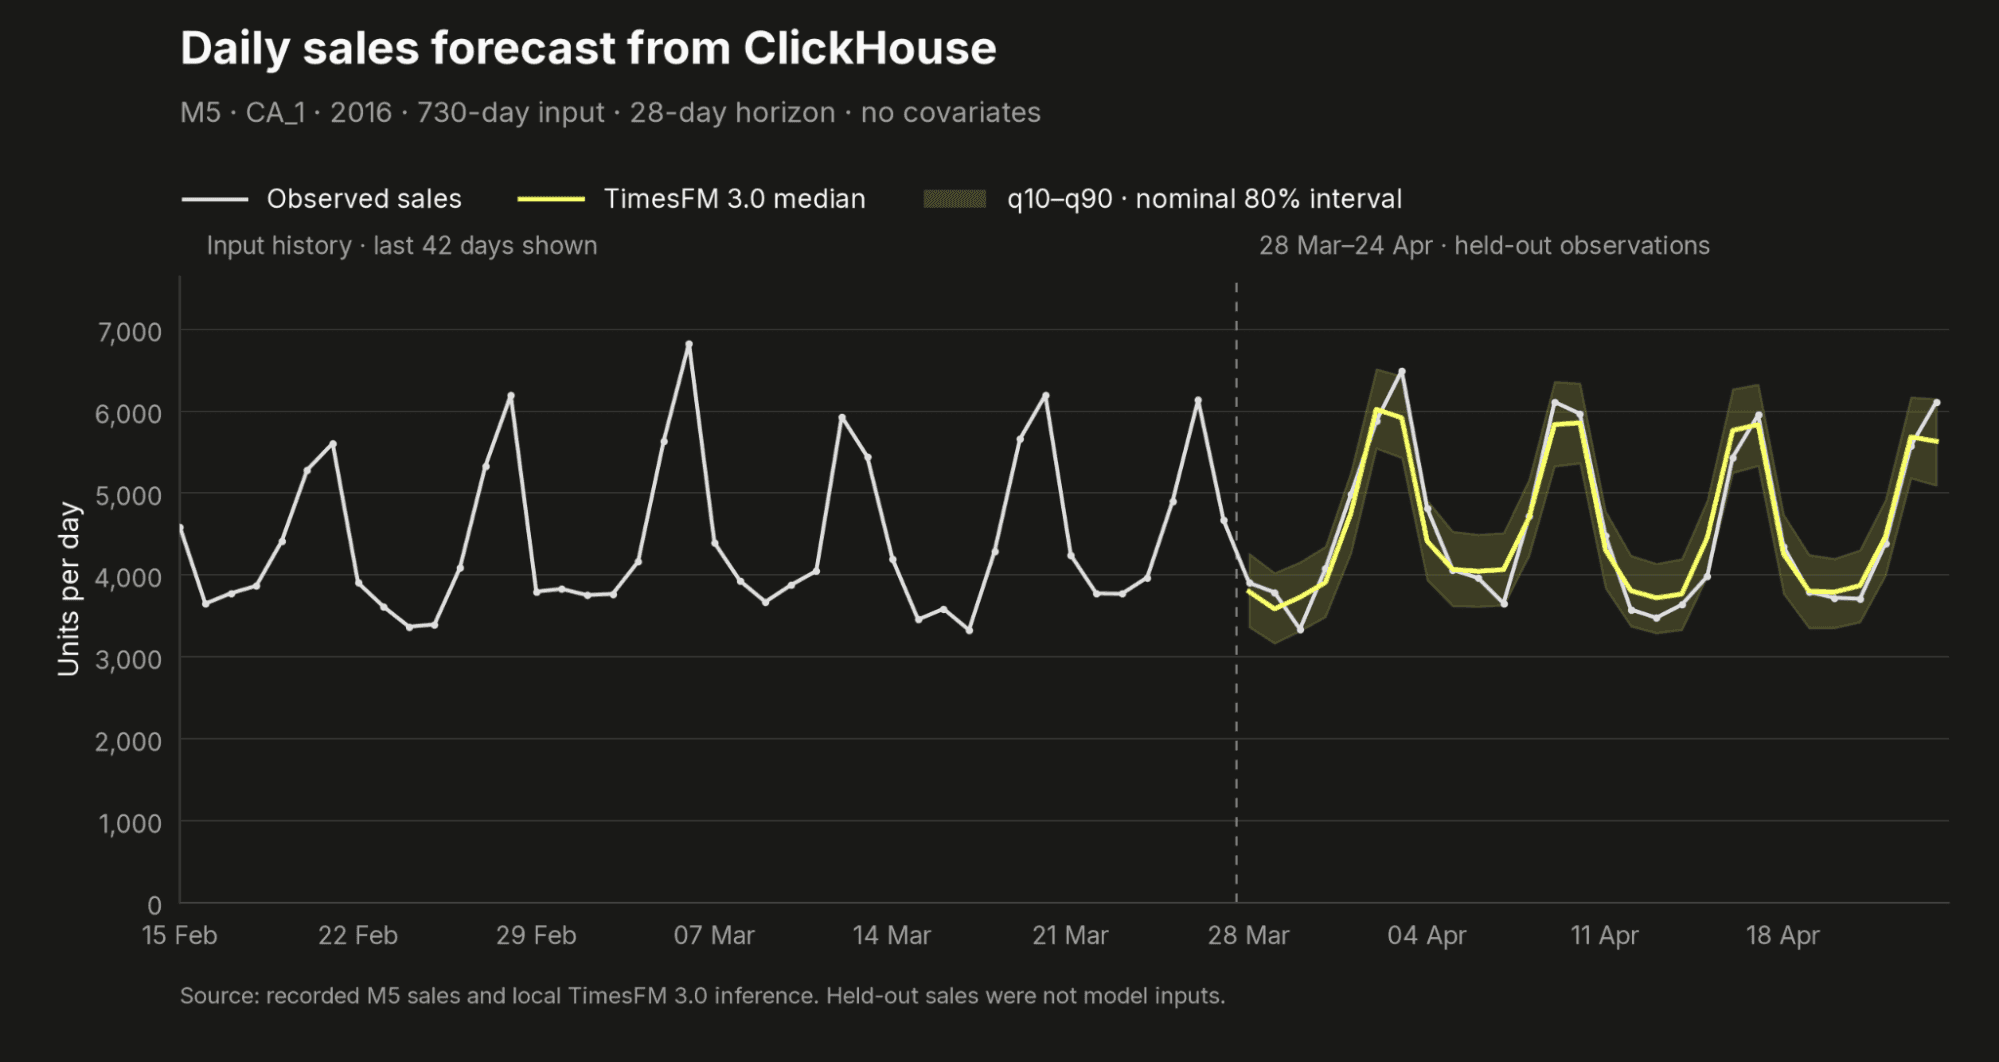
The plot shows the final 42 days of input history and the following 28 forecast days for CA_1. The white line includes observed sales in the held-out period; those observations were not provided to the model. The shaded band is the native q10–q90 interval, with nominal 80% coverage.
The returned arrays can be expanded with ARRAY JOIN and associated with future dates. From there, forecasts are ordinary query results: they can be joined to product or store dimensions, compared with subsequently observed sales, or stored in a table for downstream queries. The same query structure applies to series aggregated from transaction or event data rather than a prepared daily table.
For a stored forecast array, arrayMap(p -> aiForecastQuantile(p, 0.8), forecast) selects q80 at each future step. Choosing another quantile does not require a new forecast, and it does not change the median or the other quantiles.
Anomaly detection
Forecasts can also provide an expected value against which to compare an observation that has already arrived. aiDetectAnomalies applies that approach to historical data. It forecasts a held-out window from earlier observations, compares the forecast with the actual values, and then advances to the next window. Observations become context only after their window has been scored.
The following query scores the final 180 days in each store's input, in seven-day windows. score_last_n selects how many trailing observations receive scores; it does not limit the history available to the model. The result is aligned with the original series, so it can be combined with its dates and observed units using arrayZip:
SELECT
store_id,
point.1 AS day,
point.2 AS observed,
point.3.expected AS expected,
point.3.anomaly_score AS anomaly_score
FROM
(
SELECT
store_id,
arrayJoin(arrayZip(
arrayMap(p -> p.1, points),
arrayMap(p -> p.2, points),
aiDetectAnomalies(
arrayMap(p -> p.2, points),
'{"score_last_n":180,"horizon":7,"threshold":3}'
)
)) AS point
FROM
(
SELECT
store_id,
arraySort(p -> p.1, groupArray((day, units))) AS points
FROM m5.store_daily
WHERE day >= toDate('2013-10-28')
GROUP BY store_id
)
)
WHERE point.3.is_anomaly = 1
ORDER BY anomaly_score DESC
LIMIT 10
SETTINGS max_threads = 1;The function returns (expected, lower_bound, upper_bound, anomaly_score, is_anomaly) for each input observation. Unscored context positions have null predictions and scores. The score is the absolute forecast error divided by the distance from the median to the interval bound on that side, with a numerical floor. It is not a probability: threshold=3 filters scores above 3 rather than specifying a confidence level.
Anomaly scores always use q10 and q90 as their reference bounds. Selecting a different forecast quantile or interval for another query does not change that reference, the scores, or the anomaly threshold.
Some of the rows returned from M5 are (higher scores indicate more anomalous data):
| Store | Date | Observed units | Expected median | Anomaly score |
|---|---|---|---|---|
| TX_2 | 2015-12-25 | 0 | 3,520 | 8.65 |
| WI_3 | 2015-12-25 | 1 | 3,074 | 8.37 |
| CA_2 | 2016-03-19 | 2,779 | 6,021 | 7.82 |
| CA_2 | 2016-03-20 | 2,300 | 5,827 | 7.79 |
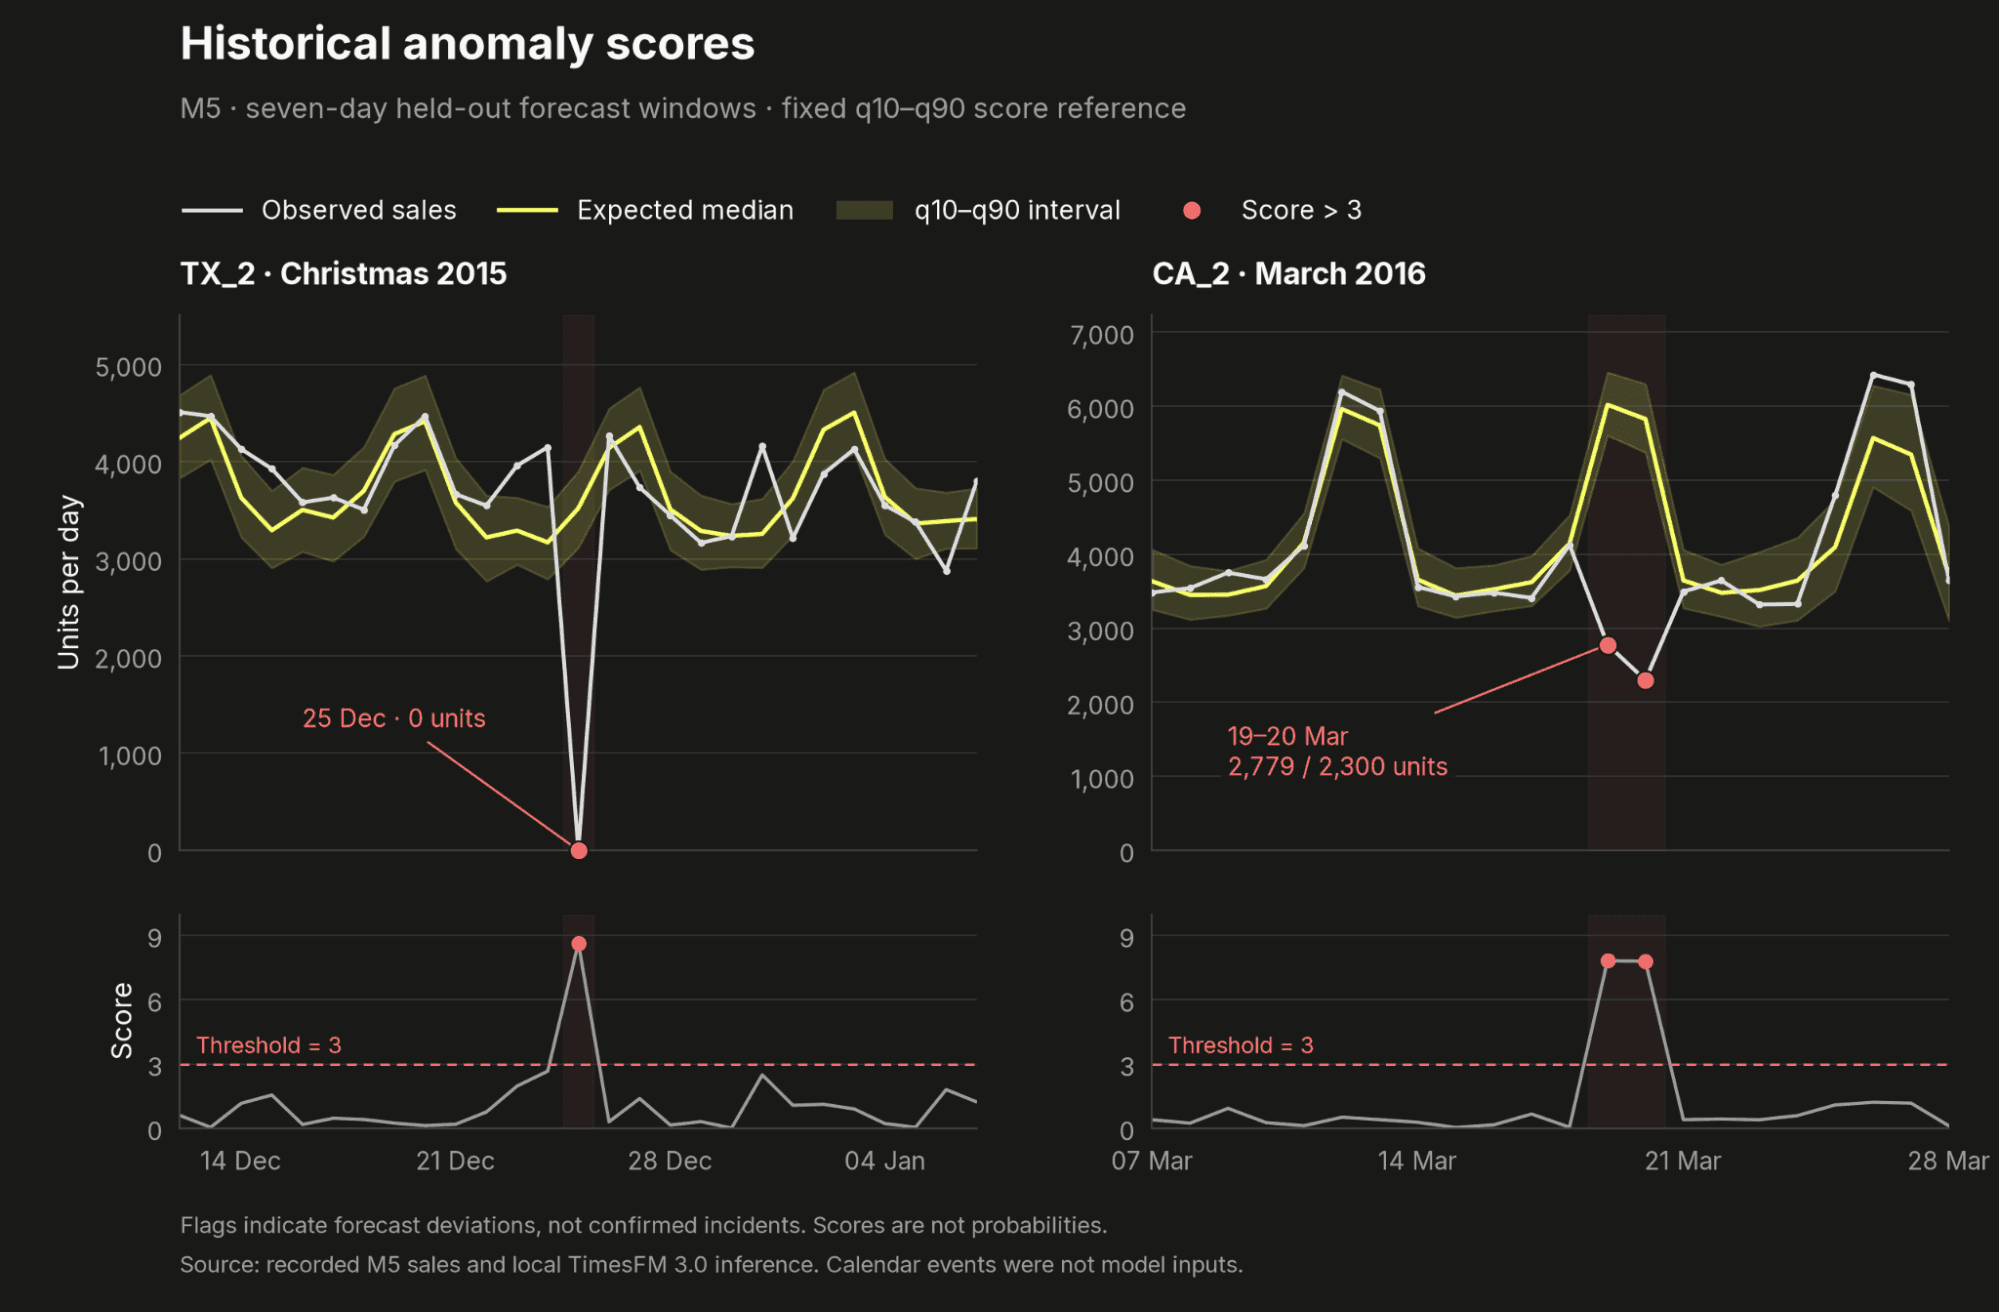
The upper panels compare observations with forecasts from preceding history. The lower panels show the corresponding normalized errors and the threshold of 3. Highlighted observations are actual values from M5, not injected events.
Christmas Day has very low recorded sales across the stores. The history-only forecast does not receive the holiday schedule. The March observations in CA_2 also fall well below the forecast, but the calendar does not identify an event on those dates. SQL can join the flagged rows to other records that might explain the change. The model score alone does not establish whether it was a stockout, a closure, or a data issue. M5 has no ground-truth anomaly labels, so these rows demonstrate the scoring workflow rather than detection accuracy.
Supplying known future events
Known-future features can describe expected events such as holidays, scheduled closures, promotions, or maintenance windows. An is_event_day flag marks the dates of a selected event in both the history and the forecast window. The model receives aligned numbers, not event names; there is no special holiday logic in the UDF. We should use separate feature channels when event types have different effects, rather than grouping every holiday or event into one flag.
As a measured example, we repeat the seven-day scoring window for December 23–29, 2015, for all ten stores, with and without the Christmas event flag. Both runs use the same 786 preceding daily observations, model checkpoint, q10–q90 score reference, and threshold of 3. The only added input is the event-day flag.
The reproduction script loads m5.event_calendar from M5's calendar.csv, with one row per date. For this experiment, is_event_day=1 when either event-name field is Christmas, and 0 otherwise. Joining the calendar to sales keeps the selected event aligned with each observation:
WITH ordered_store_history AS (
SELECT
s.store_id AS store_id,
arraySort(p -> p.1,
groupArray((s.day, s.units, c.is_event_day))
) AS points
FROM m5.store_daily AS s
INNER JOIN m5.event_calendar AS c ON s.day = c.day
WHERE s.day >= toDate('2013-10-28')
AND s.day < toDate('2015-12-30')
GROUP BY s.store_id
),
store_series AS (
SELECT
store_id,
arrayMap(p -> p.1, points) AS days,
arrayMap(p -> p.2, points) AS observed_units,
arrayMap(p -> toFloat64(p.3), points) AS event_flags
FROM ordered_store_history
),
scoring_requests AS (
SELECT
store_id,
days,
observed_units,
arrayJoin([0, 1]) AS with_calendar,
toJSONString(CAST(
(7, 7, 3, if(with_calendar = 1,
[event_flags], CAST([], 'Array(Array(Float64))'))),
'Tuple(score_last_n UInt32, horizon UInt32, threshold Float64, future_covariates Array(Array(Float64)))'
)) AS options_json
FROM store_series
),
scored_history AS (
SELECT
store_id,
with_calendar,
days,
observed_units,
aiDetectAnomalies(observed_units, options_json) AS scores
FROM scoring_requests
)
SELECT
store_id,
any(observed) AS observed_units,
round(maxIf(score.expected, with_calendar = 0), 0) AS history_only_median,
round(maxIf(score.expected, with_calendar = 1), 0) AS with_calendar_median,
round(maxIf(score.anomaly_score, with_calendar = 0), 2) AS history_only_score,
round(maxIf(score.anomaly_score, with_calendar = 1), 2) AS with_calendar_score
FROM scored_history AS h
ARRAY JOIN
h.days AS day,
h.observed_units AS observed,
h.scores AS score
WHERE day = toDate('2015-12-25')
GROUP BY store_id
ORDER BY store_id
SETTINGS max_threads = 1;toJSONString serializes the named tuple into the options object. Its future_covariates field contains one feature array: is_event_day. There are no past-only features, so past_covariates is omitted. The scoring service can see the event schedule for December 23–29 without seeing those days' sales. All that to say that this is how to provide the model with known future events to consider when producing a forecast.
Christmas Day scores fall below the unchanged threshold in nine of ten stores. All ten are flagged in the history-only run. For the two Christmas examples:
| Store | Observed units | History-only median | With calendar median | History-only score | With calendar score |
|---|---|---|---|---|---|
| TX_2 | 0 | 3,520 | 1,384 | 8.65 | 2.71 |
| WI_3 | 1 | 3,074 | 749 | 8.37 | 1.45 |
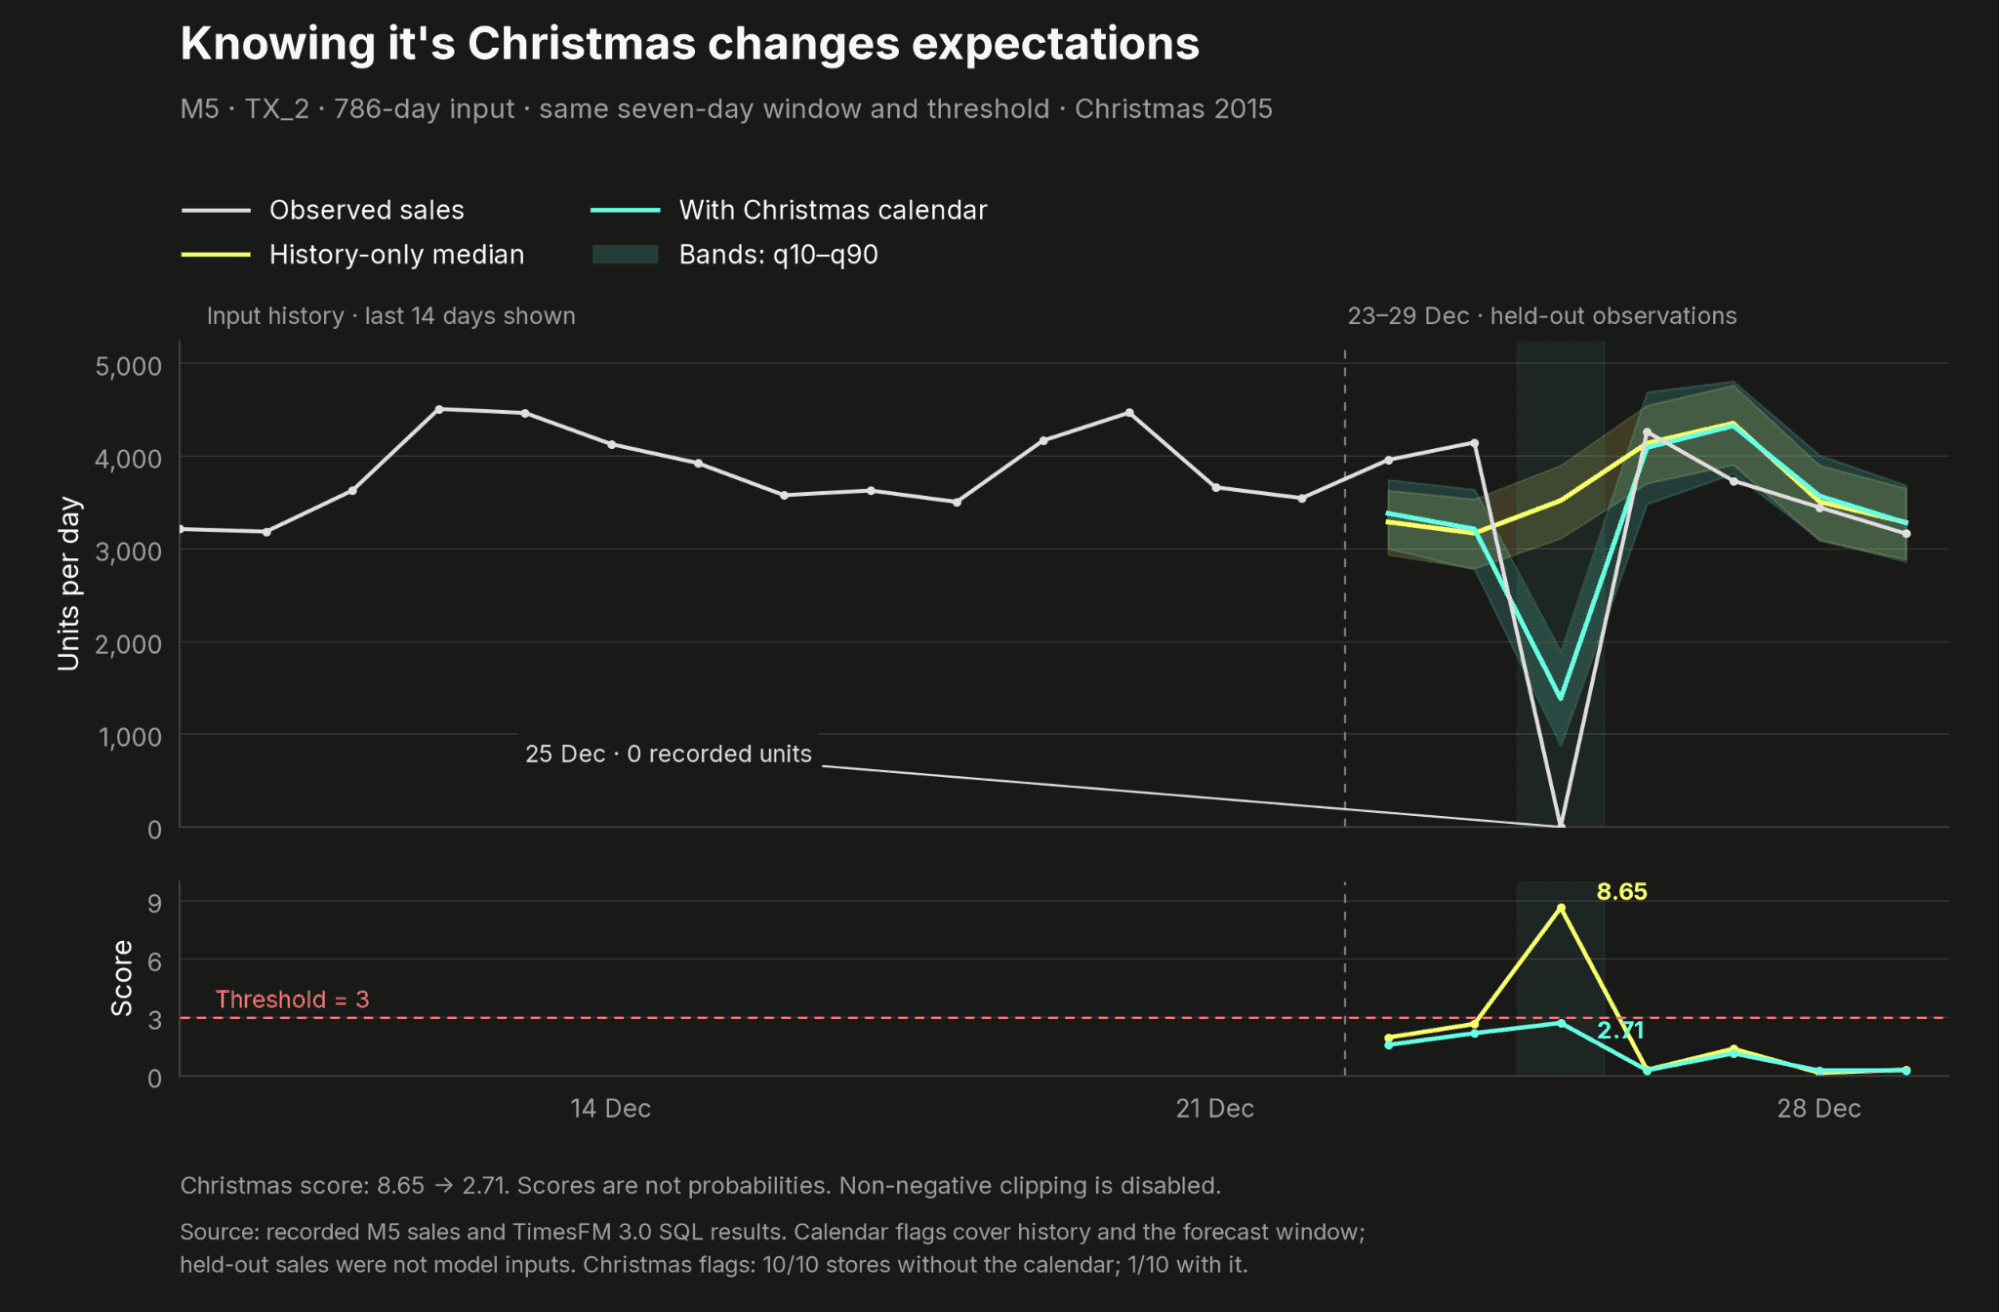
The calendar helps the model anticipate the dip, but does not fully predict near-zero sales. TX_2's zero sales still falls below the calendar-aware q10 bound of 874 units; its normalized error no longer exceeds 3. CA_2 remains flagged, with a score of 3.50. This is a separate, calendar-aware comparison, not a change to the history-only results above, and does not establish general anomaly detection accuracy.
Using the results in an analytics workflow
This interface fits the work already done in a real-time analytics system or data warehouse. Transaction and event data can be aggregated into a regular series in ClickHouse, optionally using materialized views to maintain those aggregates as data arrives. A query selects the history and invokes inference while the returned predictions remain available to SQL for filtering, joins, and further aggregation.
For a recurring workflow, forecast results can be stored with their forecast origin and model revision, then compared with actual values as new data arrives. Recent observations can be scored in a bounded trailing window while retaining earlier history as context. That avoids rescoring the entire table on every run. The demo does not schedule these queries or maintain forecast tables automatically; those are separate choices for the application.
The model service is still an external dependency on the query path. Context length, series count, inference capacity, and request timeouts need to be bounded. The SQL examples use historical data and do not establish streaming latency or production throughput. Interval coverage and scoring thresholds also need to be checked for the intended use.
Conclusion
We connected ClickHouse to a time-series foundation model and used SQL to forecast demand, detect anomalies, and supply known-future events that help explain expected changes. ClickHouse prepares and orders the data, while the model supplies forecasts without per-series training. Predictions return as ordinary query results, ready for joins, filtering, and further time-series analysis in the database.
The same SQL-to-model approach could connect ClickHouse to tabular foundation models for predictions on structured rows. In a future post, we'll explore how to prepare tabular inputs in ClickHouse, call a tabular foundation model, and use its predictions in SQL.
Get started today
Interested in seeing how ClickHouse works on your data? Get started with ClickHouse Cloud in minutes and receive $300 in free credits.
Sign up