

pg_stat_ch,
the open-source Postgres extension that streams per-statement counters into
ClickHouse Cloud. Telemetry is normalized inside Postgres before it leaves
the database — literals are stripped and replaced with placeholders, so the
exact values you query never enter the telemetry stream.
Open query insights
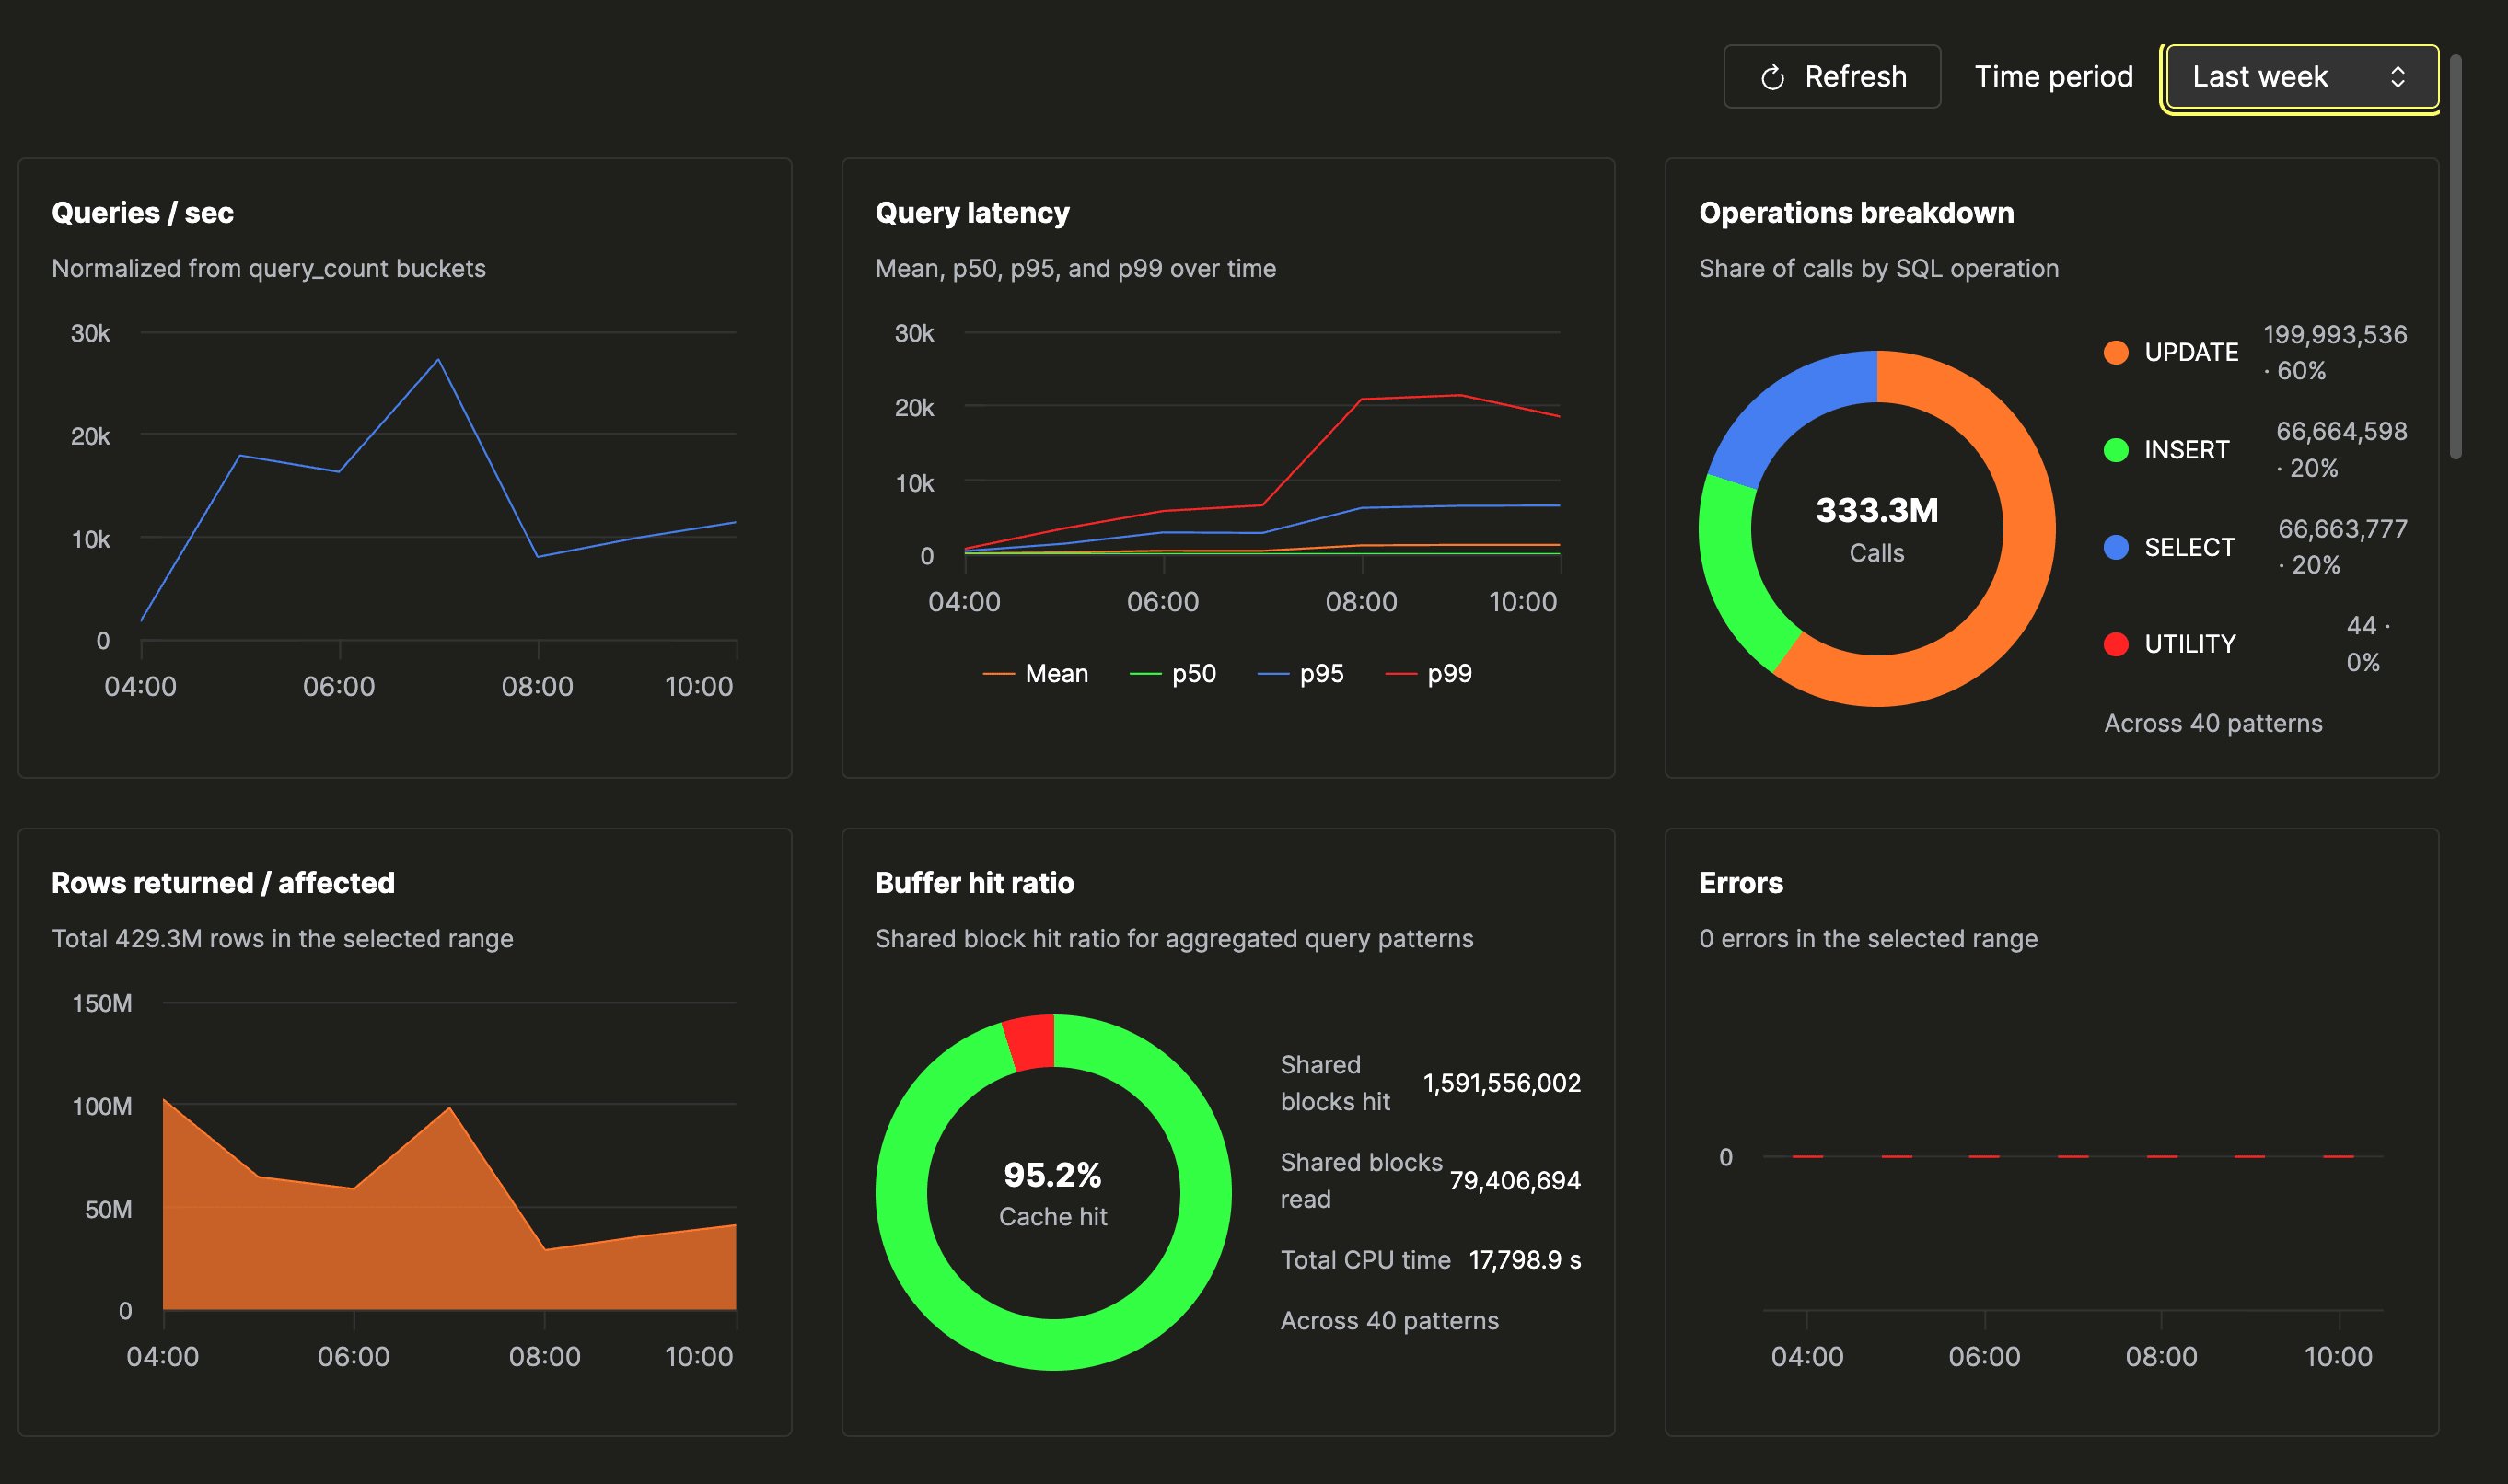
Open your ClickHouse Managed Postgres instance in the cloud console and click Query insights in the left sidebar. The page is divided into five surfaces, in the order you’d actually use them:- An Overview that fits a database health check on one screen.
- A Slow patterns table that ranks every query pattern your database has run, sorted by whatever you suspect.
- A Recent queries panel that lists individual executions in reverse chronological order.
- A Waits tab that ranks the wait events active sessions spent time in, with a Blocking queries table that shows which sessions blocked queries waiting on locks.
- A Detail flyout that aggregates every counter for a single pattern.
Overview
The overview is a 3×3 grid of nine panels. The first two rows cover query activity:
One screen tells you whether the database is healthy. A healthy instance
has a familiar shape — buffer hit ratio in the high nineties, query volume
moving with application traffic, error rate flat or zero, and percentile
latencies tracking each other closely.
Wait charts
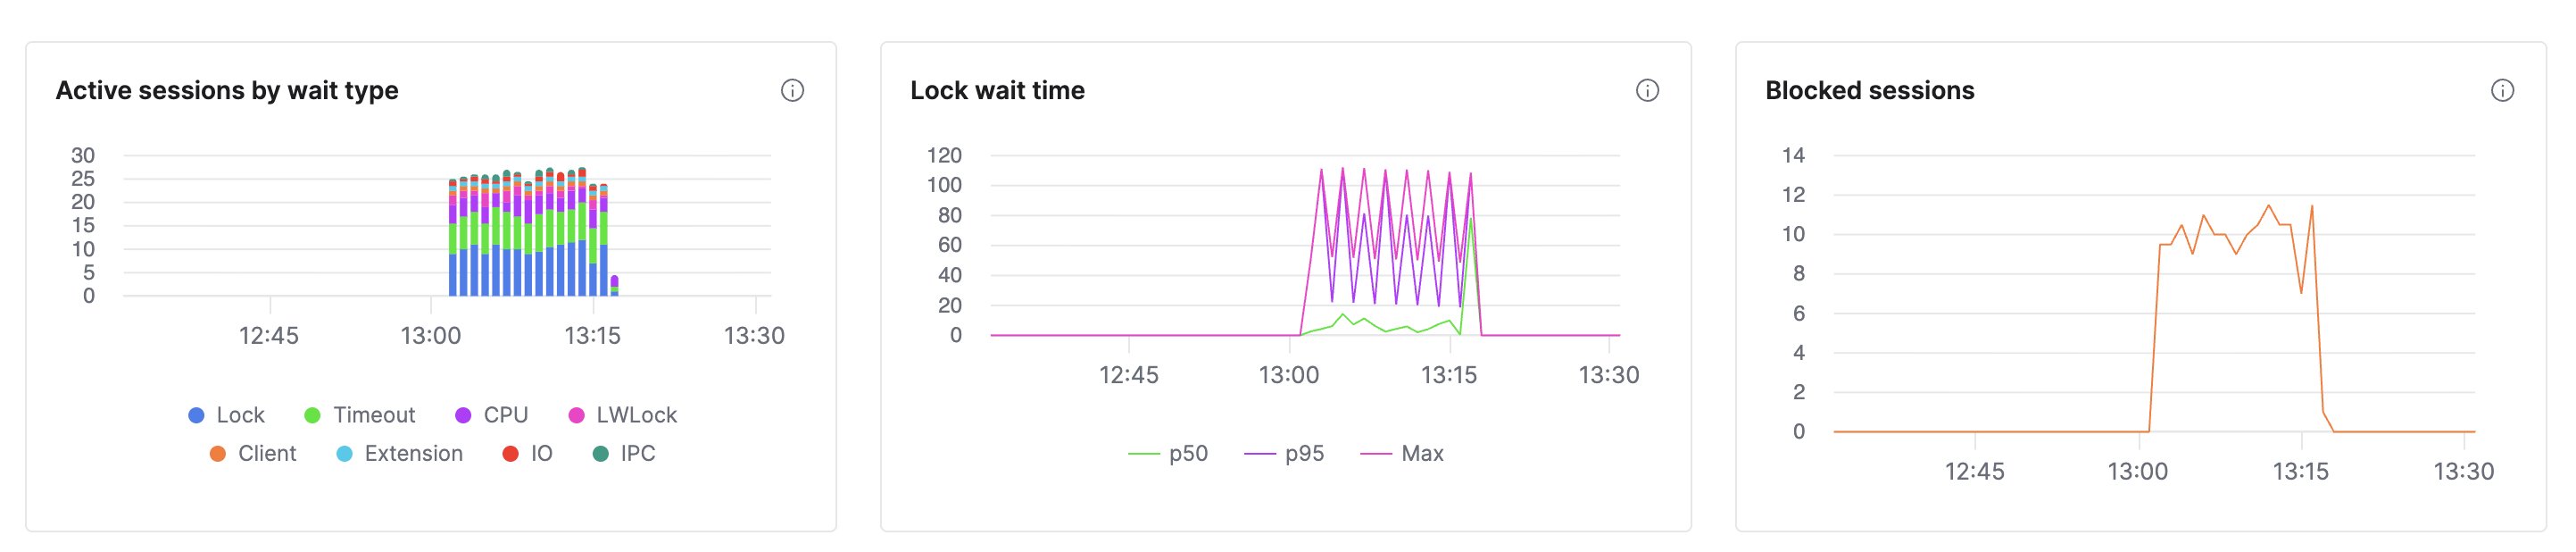
The third row shows what active sessions on the primary were waiting on, from samples taken every 30 seconds:
Look for Blocked sessions staying above zero while Lock wait
time rises: this can indicate sustained lock contention. Click
Active sessions by wait type to open the Waits tab.
Slow patterns
When the overview points at trouble, the patterns table is where the investigation starts. One row per normalized query pattern, with the literals stripped out so executions of the same statement collapse onto the same row.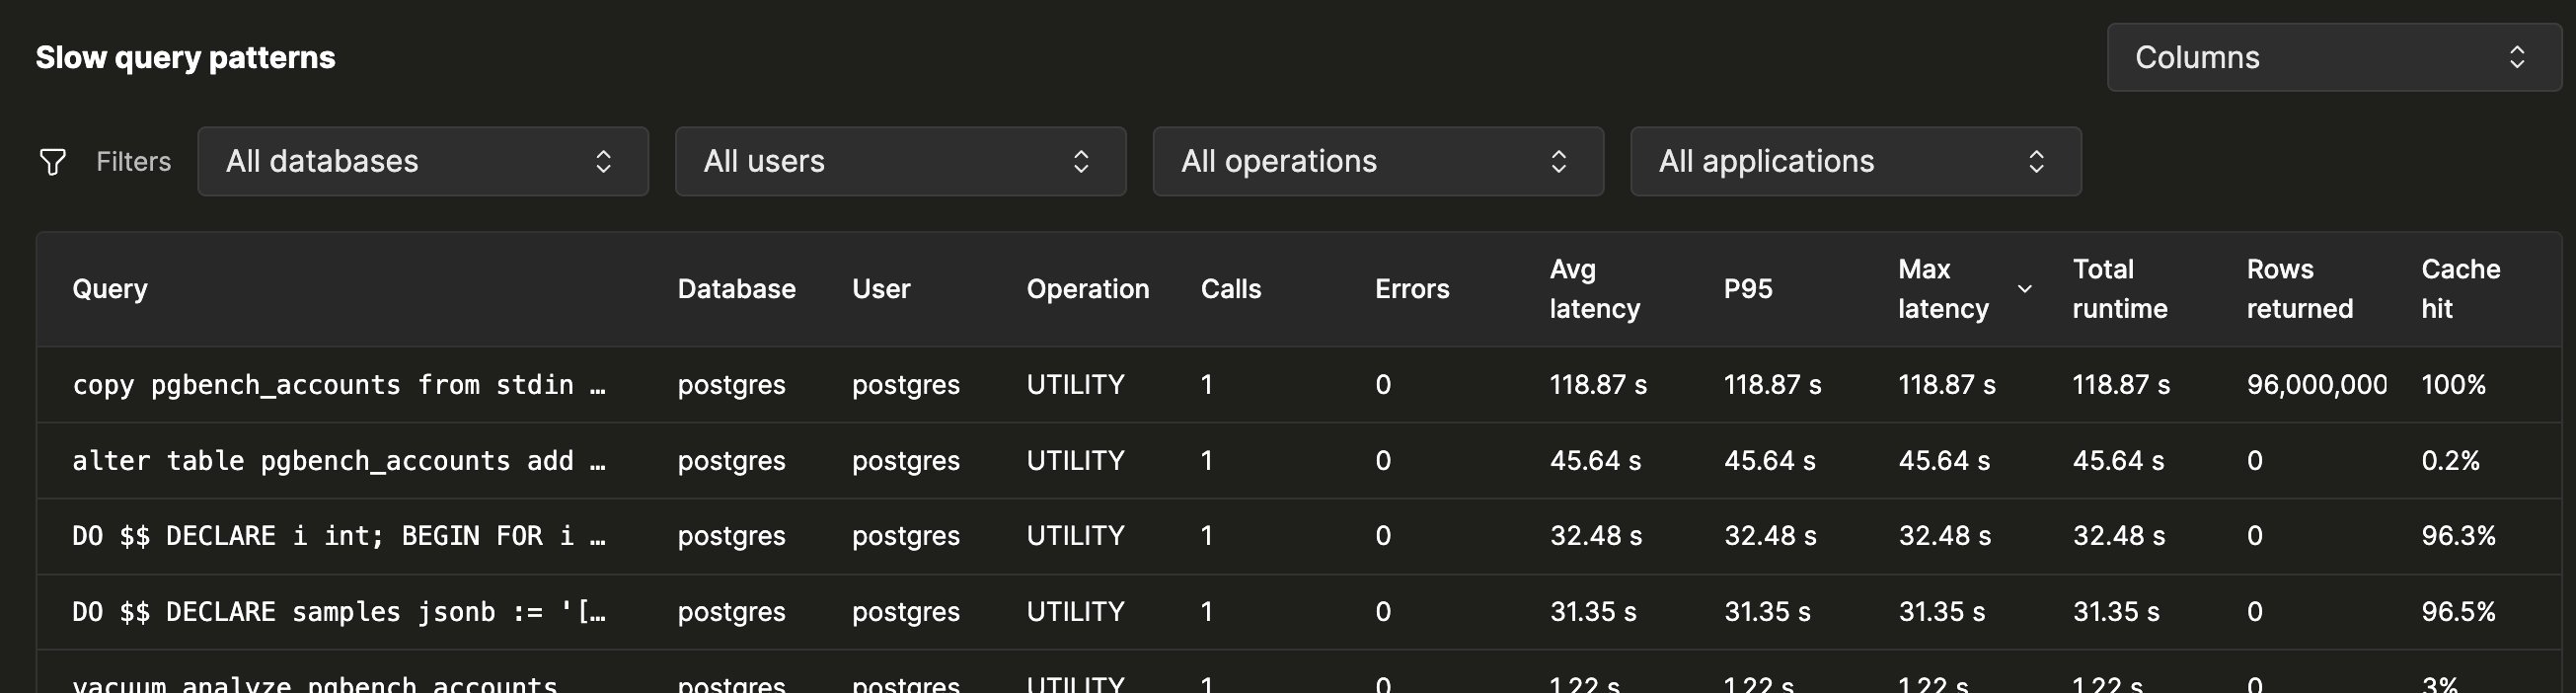
Sort by what you suspect
The table defaults to Total runtime descending — when you sort this way, the top pattern is usually the answer to “what is costing me the most?” It may not be the slowest pattern individually. A query that runs eight million times a day at twelve milliseconds can matter more than one that ran once at three seconds. Each sort gives you a different lens:- Total runtime — where the database spent the most wall-clock time.
- CPU time — compute-heavy patterns.
- Calls — high-frequency patterns.
- Errors — repeated failures.
- Avg / P50 / P95 / P99 / Max latency — outliers, by percentile.
- Rows returned, Blocks read, Blocks hit, WAL bytes — patterns that moved the most data through the engine, the cache, or the write-ahead log.
Narrow the table
Filter the table to whichever slice of your workload you’re investigating:- Database
- User
- Operation (
SELECT,INSERT,UPDATE,DELETE, …) - Application — the
application_namefrom the connection string
sales db”
becomes two dropdowns. Filter values auto-populate from what your
instance has actually run.
Recent queries
Below the patterns table, the Recent Queries panel lists individual executions in reverse chronological order — one row per executed statement, not one row per pattern. Use it when you want the raw event stream instead of an aggregate, for example to spot-check that a fix landed or to find the exact moment an error fired.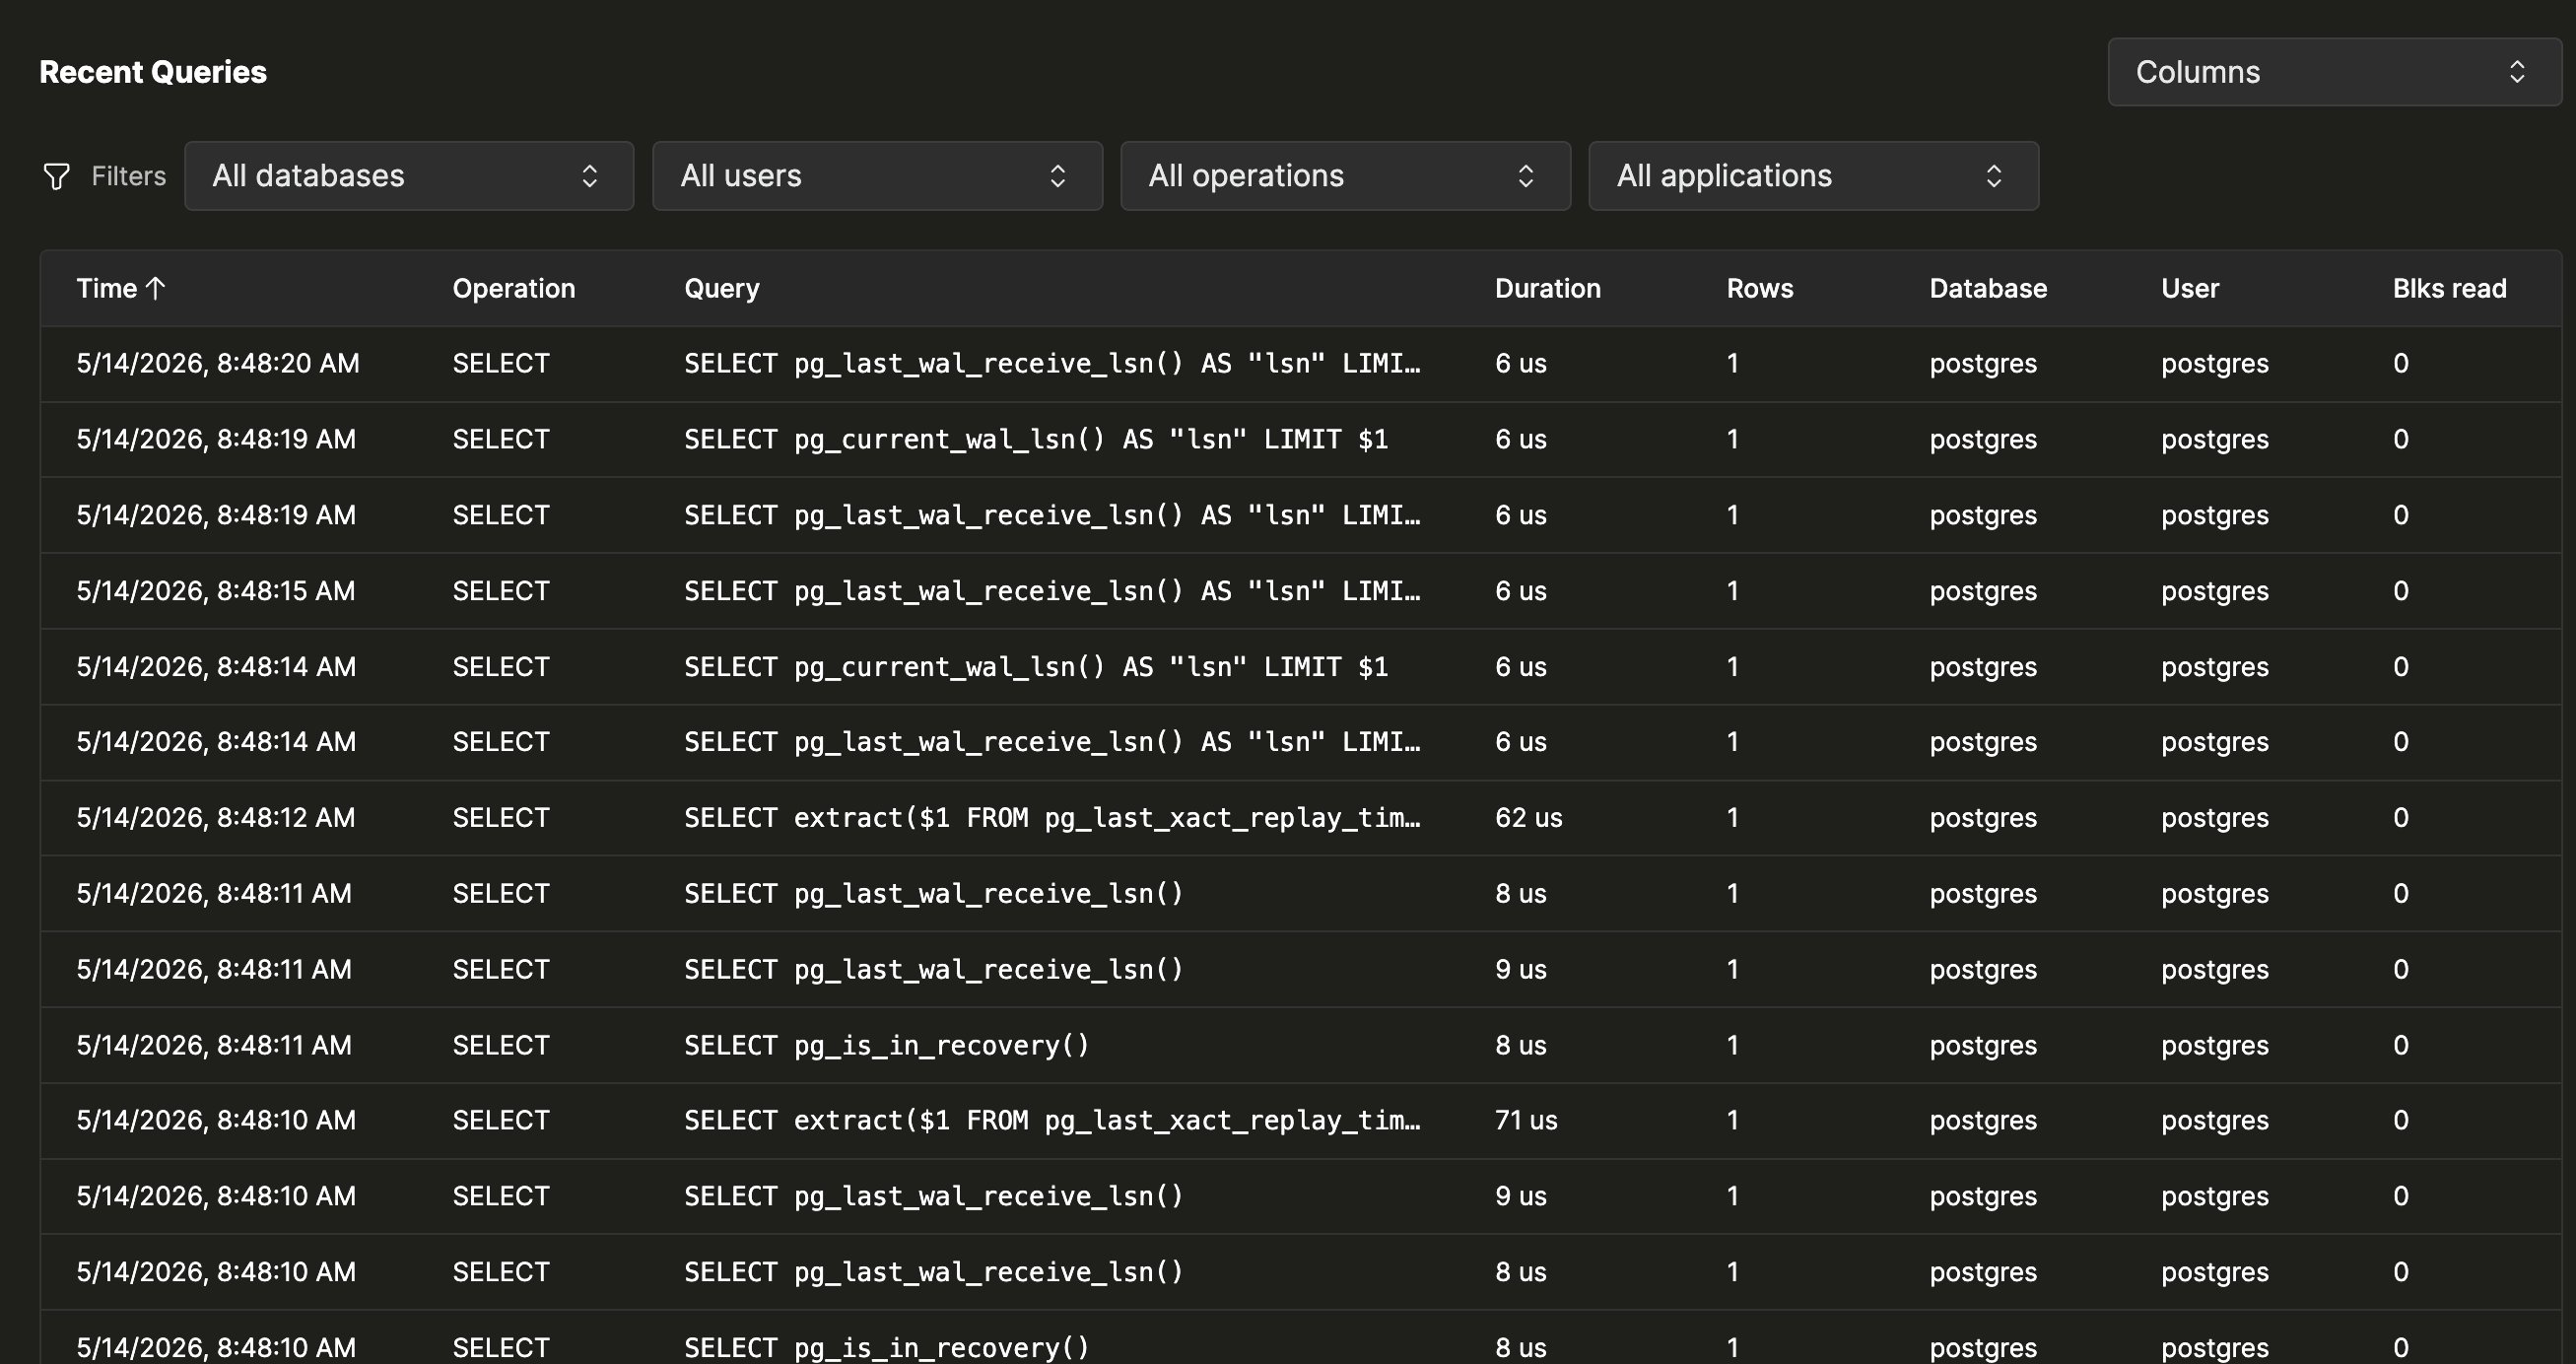
Waits
Open the Waits tab, or click Active sessions by wait type in the wait charts, to see the same chart and a Wait events breakdown table that ranks wait events by average active sessions over the selected time period.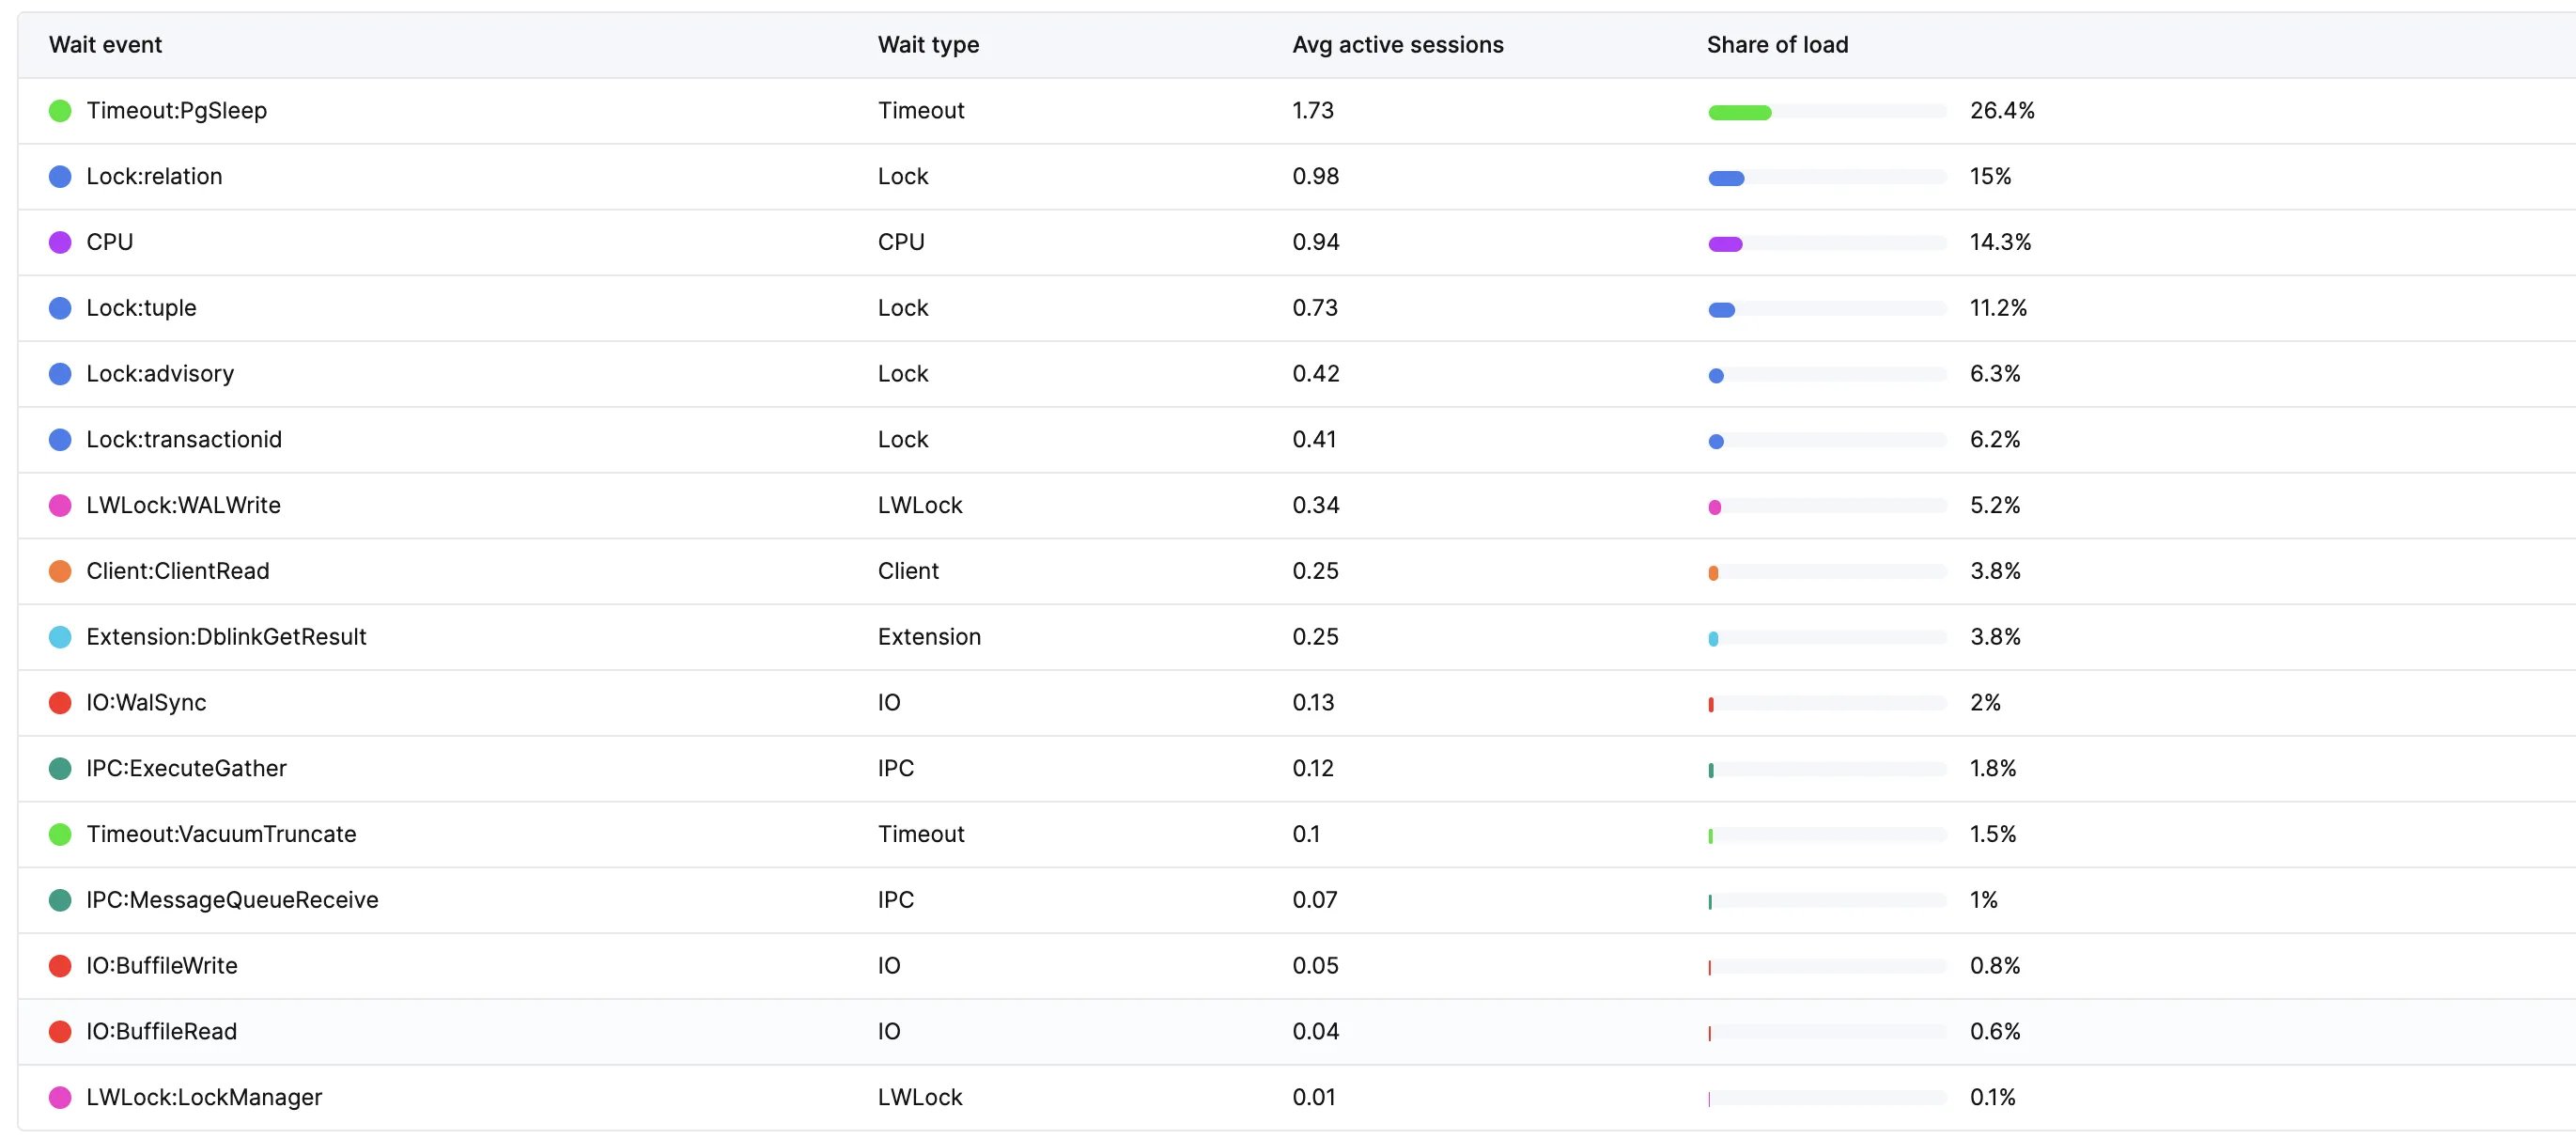
For descriptions of individual events, see the
Postgres wait events reference.
Blocking queries
Below the wait events table, Blocking queries shows which queries waited on locks and which sessions blocked them. A blocking session either holds a conflicting lock or is ahead in the queue waiting for one. Each row pairs a waiting query with its direct blocker and can combine samples from several sessions. The most frequently seen pairs come first. Collection is off by default. To start collecting, turn on the Enable switch next to the Blocking queries title. Only users who can manage the service can turn collection on or off, and read replicas follow the primary’s setting. Sampling usually starts within about a minute.
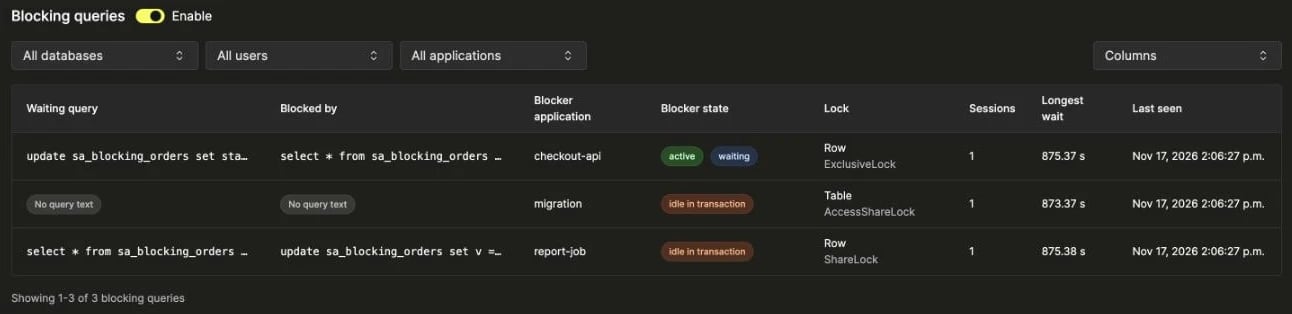
Open the Columns picker for the users, applications, and PIDs of
the waiting sessions, and the users and PIDs of the blocking sessions. Filter the
table by the waiting sessions’ database, user, or application.
A blocker in
idle in transaction is often the one to fix first: it
opened a transaction, took locks, and hasn’t committed or rolled back.
Its Blocked by text is its most recent statement, which may not be
the one that took the lock.
No query text means Query Insights has no text for that statement.
This happens when the blocking session’s last statement was a utility
command such as LOCK TABLE, when a query waits for a table lock
before Postgres has assigned it a query ID, or when Query Insights
hasn’t recorded a completed run of the statement. Query Insights also
hides the text of statements from sessions the service uses internally,
such as for monitoring and replication. The row still shows the
application, state, and lock. Prepared transaction in Blocked
by means a prepared transaction holds the lock, so there is no
blocking session to describe.
Detail flyout
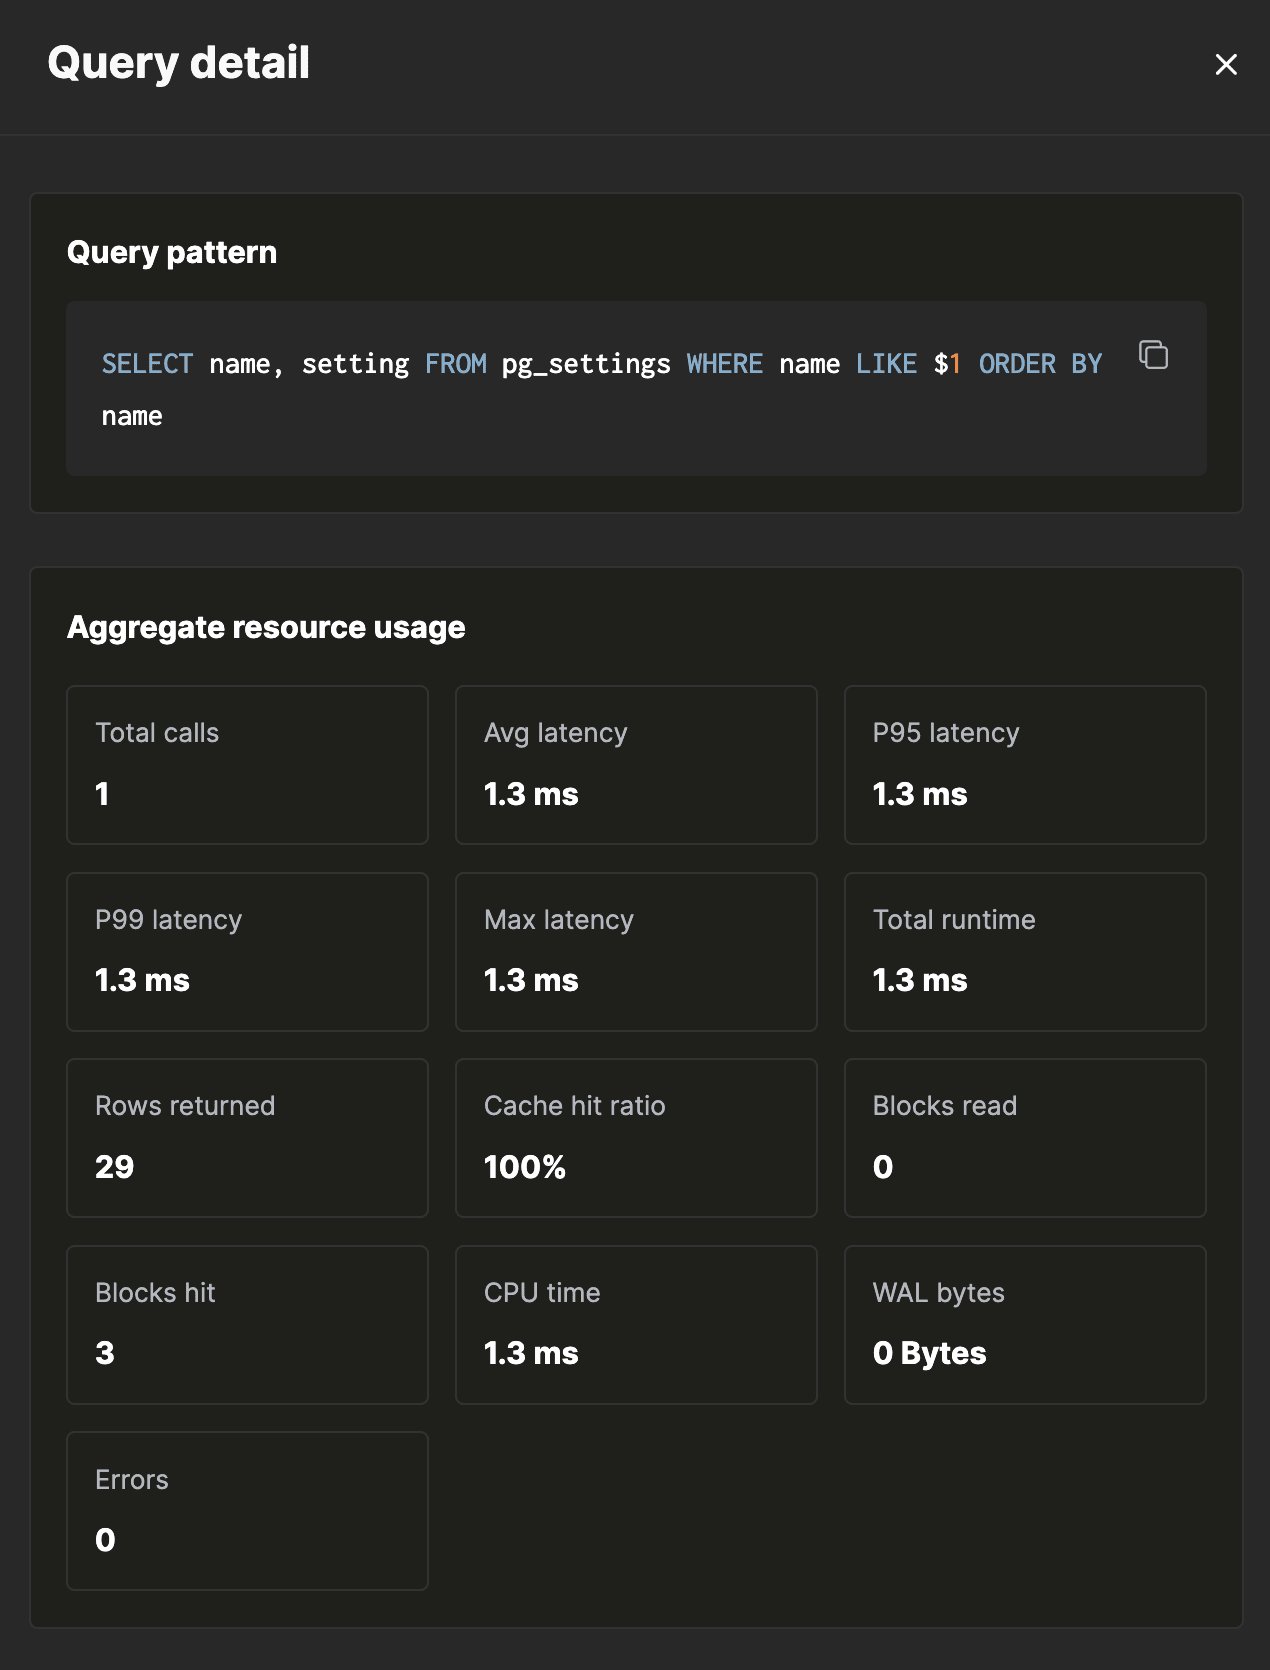
Click any row in the patterns or recent queries table and the Query detail flyout opens on the right. The flyout takes every execution of that pattern over the selected time range and aggregates the counters that explain why it’s slow. The flyout is a single scrolling layout with five sections:- Query pattern — the normalized SQL with literals replaced by
$1,$2, … and a copy-to-clipboard button. - Aggregate resource usage — a grid of 13 stat cards covering total calls, avg/P95/P99/max latency, total runtime, rows returned, cache hit ratio, blocks read, blocks hit, CPU time, WAL bytes, and errors.
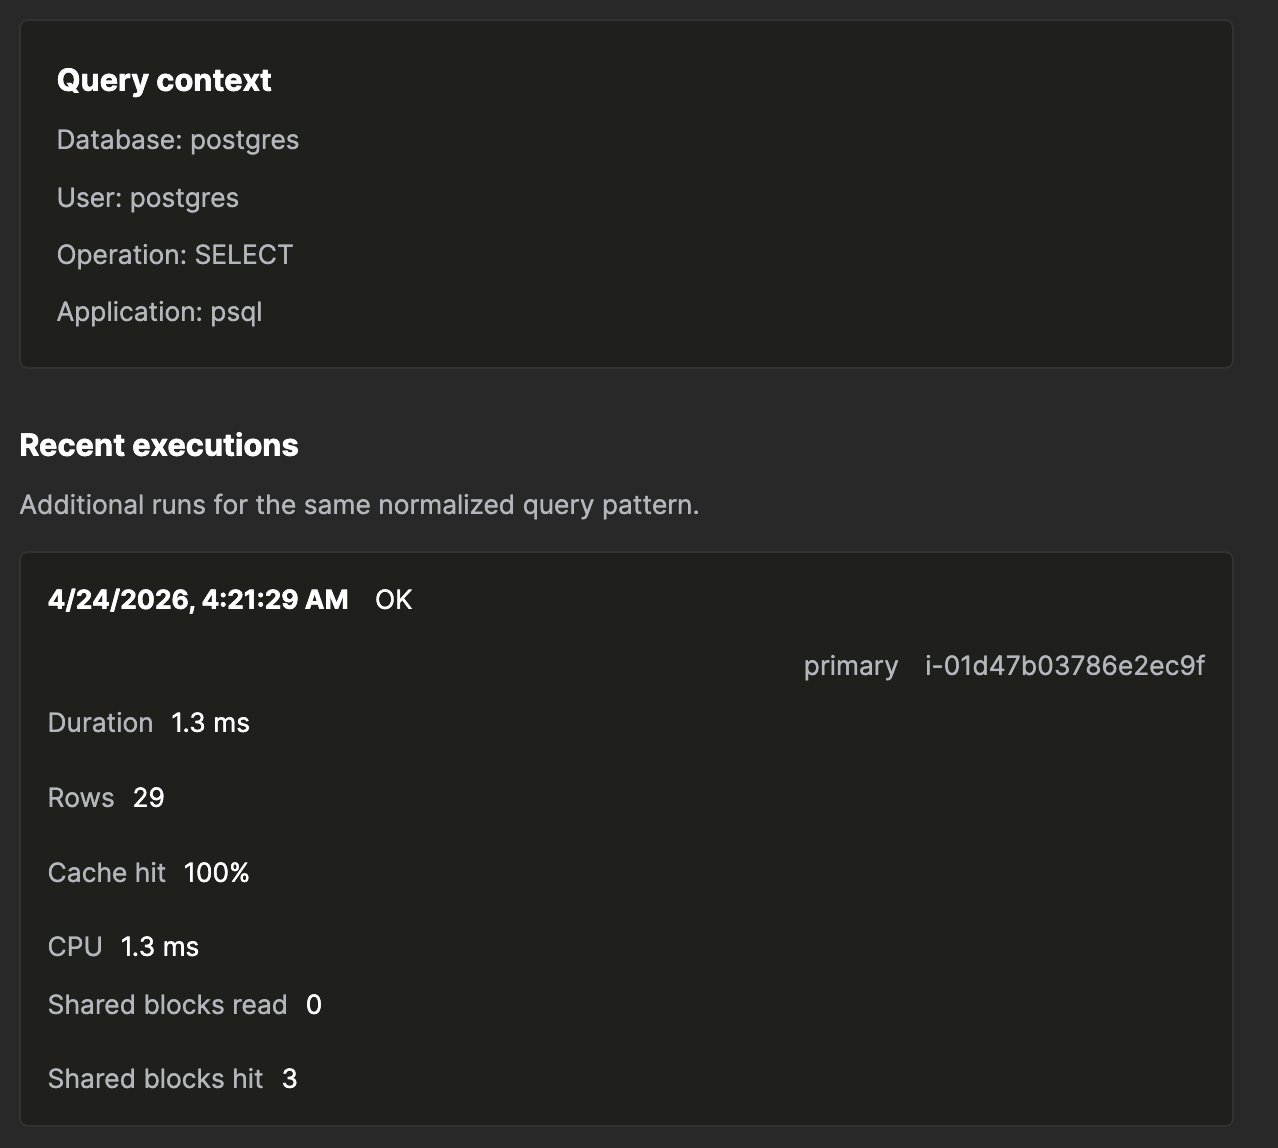
- Query context — the database, user, operation, and application this pattern came from.
- Notable executions — errors, unusually slow runs, and large-result executions, surfaced before the full recent list.
- Recent executions — the individual runs of the same pattern, with per-execution counters.
Per-execution counters
Expand a recent execution and you get the counters that pinpoint where the time went:- Shared blocks — read and hit always shown; written and dirtied shown when non-zero.
- Local and temp block ops — non-zero temp block ops mean a sort or hash spilled to disk.
- Read / write time — I/O time, separately from CPU time.
- CPU time — user and system, separately.
- Parallel workers — planned vs. actually launched.
- JIT — total JIT compilation time and function count.
- WAL — bytes and record count.
Query insights API
Per-statement telemetry is also available through the ClickHouse Cloud OpenAPI. The Slow patterns table maps to the list slow query patterns endpoint, and the detail flyout maps to the get slow query pattern endpoint, which returns one pattern’s aggregate metrics together with its recent executions. The Blocking queries table maps to the list blocking queries endpoint.How it works
Normalized in Postgres, before the wire
pg_stat_ch hooks the parse-analyze phase, swaps each literal for a
placeholder ($1, $2, …), and caches the resulting pattern in a
per-backend LRU keyed by queryid. When the executor finishes the
statement, that cached pattern is what gets attached to the event. The
exact statement with values never leaves the database.
Out of the way of the database
The producer adds roughly 3% overhead per statement. The enqueue path uses a non-blocking try-lock on a shared-memory ring buffer. Under pressure, the extension drops events with a counter rather than back-pressuring Postgres.Waits are sampled
The wait charts and Waits table use samples collected every 30 seconds on the primary. Short waits can occur entirely between samples and may not appear, so these views are most useful for identifying sustained waits and lock contention. Blocking queries are sampled every 30 seconds too, on each instance where collection is on, so a lock held for only a few seconds may not appear. Each sample records query IDs, not query text. The text in the table comes from the normalized patterns Query Insights already collects, so literal values never appear.Raw events, not aggregates
pg_stat_ch emits one raw event per executed statement (top-level and
nested), subject to sampling. Query percentiles, rankings, and
breakdowns are computed in ClickHouse from this event stream.
Same engine our customers use
The Insights backend is ClickHouse Cloud. Per-query telemetry from a busy Postgres instance is millions of rows a day; columnar compression keeps months of per-execution detail cheap to retain, and sub-second aggregations over billions of rows keep the UI interactive as you slice across a week or a month.Open source
pg_stat_ch is Apache 2.0. Run it against any Postgres, ship to any
ClickHouse. Source and issues live at
github.com/clickhouse/pg_stat_ch.
Related pages
- Monitoring dashboard — built-in resource and activity charts
- Prometheus endpoint — scrape host-level metrics into your own observability stack
- ClickHouse Managed Postgres OpenAPI — query slow patterns, recent executions, and blocking queries programmatically
- Extensions — the extensions available on ClickHouse Managed Postgres instances
pg_stat_chon GitHub — the open-source extension that powers Query Insights