

JOIN clause reference. For execution algorithms and algorithm selection, see JOIN algorithms.
Prefer avoiding JOINs
ClickHouse supports a wide variety of JOIN types and algorithms. However, JOINs are inherently more expensive than querying from a single, denormalized table. Denormalization shifts computational work from query time to insert or preprocessing time, which often results in significantly lower latency at runtime. For real-time or latency-sensitive analytical queries, denormalization is strongly recommended. In general, denormalize when:- Tables change infrequently or when batch refreshes are acceptable.
- Relationships are not many-to-many and do not have excessively high cardinality.
- Only a limited subset of the columns will be queried, i.e. certain columns can be excluded from denormalization.
- You have the capability to shift processing out of ClickHouse into upstream systems like Flink, where real-time enrichment or flattening can be managed.
When JOINs are required
Follow these best practices to improve JOIN performance:- Use
ANYJOINs when only one match is needed. A regular JOIN returns every matching row and can produce a Cartesian product for duplicate keys. To enrich each left-hand row with one matching right-hand row, useLEFT ANY JOIN, which reduces result size and memory use. To check whether a matching row exists, useINorLEFT SEMI JOIN. With the defaultany_join_distinct_right_table_keys = 0, anINNER ANY JOINalso limits the left-hand side to one row per key, so it can drop left-hand rows that share a key. SeeALLandANYstrictness. - Reduce both sides before the JOIN. Apply selective conditions in
WHEREandJOIN ONclauses. ClickHouse pushes filters down when possible, but explicit subqueries can ensure that each input is filtered before the JOIN. - Consider
INinstead ofINNER JOIN. When a query only needs to test whether a key exists in the other table, anINsubquery expresses that requirement directly and can use less memory than producing anINNER JOINresult. - Use dictionaries for repeated key-value lookups. With a layout such as
HASHEDorCOMPLEX_KEY_HASHED, a dictionary is loaded into memory ahead of the query and refreshed according to itsLIFETIME. ThedictGetOrDefaultfunction looks up each key in the dictionary without a JOIN, for exampledictGetOrDefault('stackoverflow.users_dict', 'DisplayName', tuple(p.OwnerUserId), ''). - Prefer the
Jointable engine for reusable lookups. TheJointable engine stores a precomputed in-memory structure for a declared JOIN type, strictness, and key. In ClickHouse Cloud, it is implemented asSharedJoinwith aMergeTreebacking table, andJoin(ANY, LEFT, key)provides an updatable per-key lookup. See Fast, updatable lookups with the Join table engine. - Join on table sorting keys when possible. When both tables are physically ordered by the JOIN key,
full_sorting_mergecan skip sorting and reduce memory use. Confirm the execution plan and benchmark this algorithm against the default on representative data. - Avoid disk-spilling JOINs. Spilling intermediate JOIN state to disk can keep a query within its memory limit, but disk I/O usually increases latency. Hash joins can switch to grace hash at configured spill thresholds, while merge joins can use external sorting. Reduce input rows and columns or change the data model before relying on spilling. See Choosing the optimal JOIN algorithm for details.
- Use default values as no-match markers when appropriate. The default
join_use_nulls = 0fills unmatched outer JOIN columns with their data type’s default value and avoidsNullablewrappers. Enablejoin_use_nullsonly when the query must distinguish an unmatched row from a matched row containing a default value.
Choosing the optimal JOIN algorithm
ClickHouse supports several JOIN algorithms that trade off between speed and memory. The default value ofjoin_algorithm is direct,hash,ie_join, and ClickHouse selects the first applicable algorithm for the JOIN type, strictness, condition, and table engine. Consider changing it only after reducing both inputs and when measurements on representative data show that a different memory or execution strategy is needed. For algorithm execution details and supported JOIN types, see JOIN algorithms.
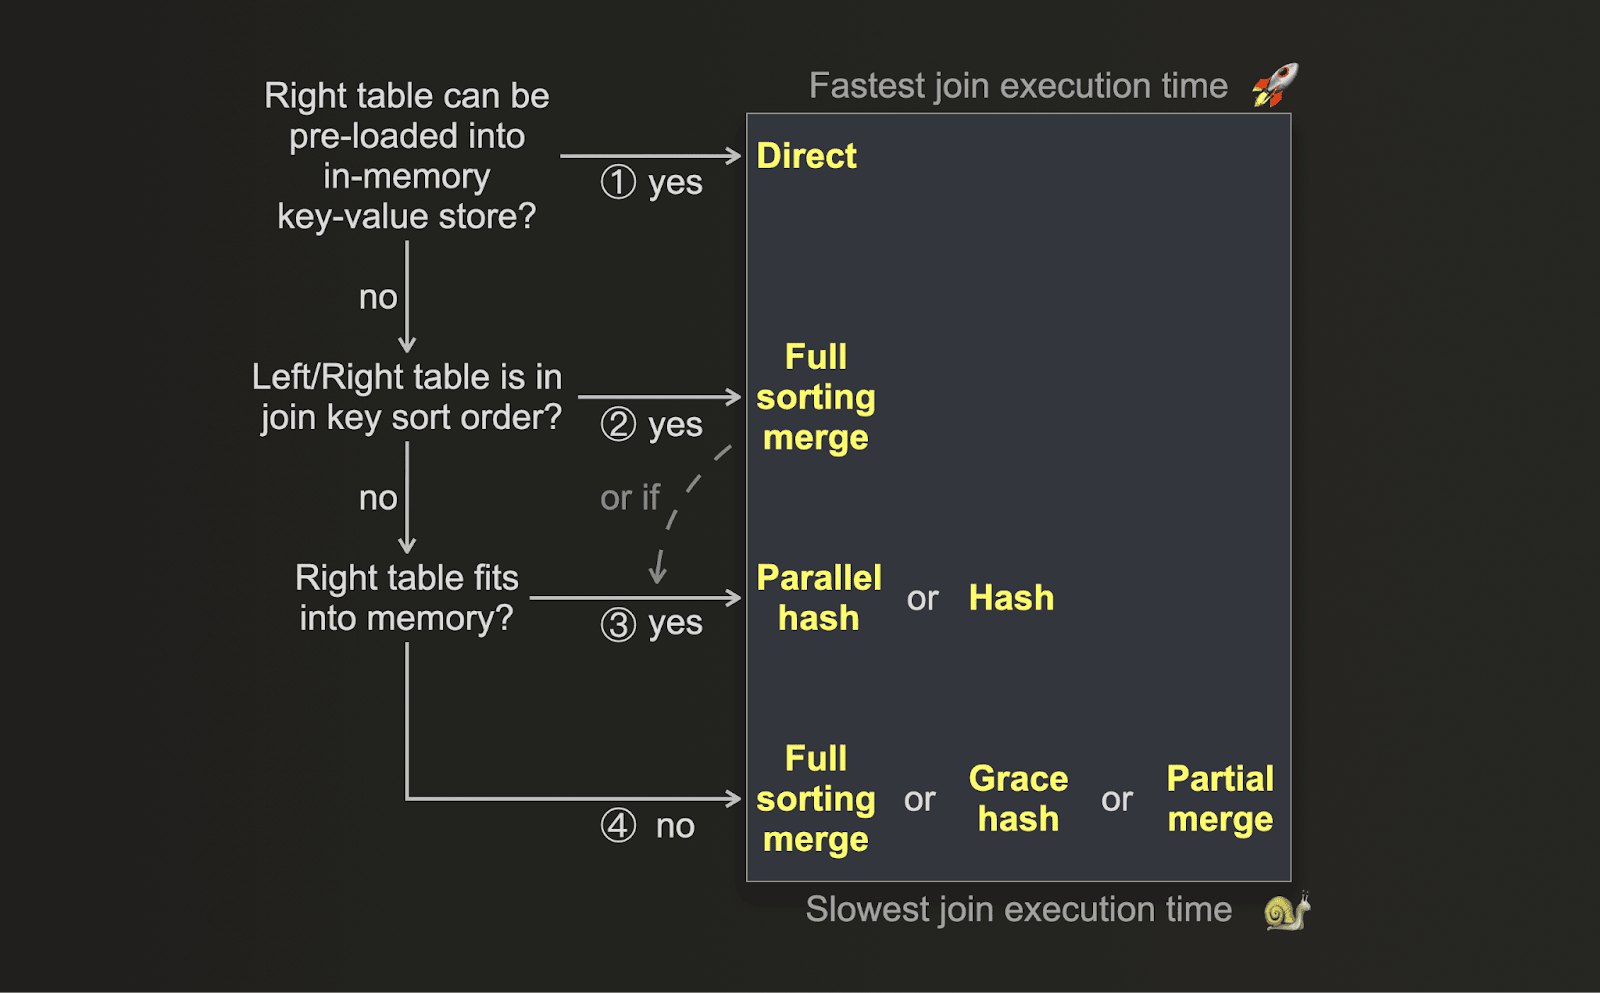
If your key optimization metric is performance and you’re looking to execute the join as fast as possible, then you can use the following decision tree for choosing the right join algorithm:
-
(1) If the right-hand side is a dictionary or another storage with low-latency key-value lookups, the
directalgorithm is applicable and is often the fastest approach. It requires anINNER JOIN,LEFT JOIN,LEFT ANY JOIN,LEFT SEMI JOIN, orLEFT ANTI JOINwhoseONclause contains only one equality condition on the single-column key of the storage, and otherwise ClickHouse uses the next algorithm injoin_algorithmwithout an error. - (2) If your table’s physical row order matches the join key sort order, then it depends. In this case, the full sorting merge join skips the sorting phase resulting in significantly reduced memory usage plus, depending on data size and join key value distribution, faster execution times than some of the hash join algorithms.
-
(3) If the right table fits into memory, use the
hashalgorithm. It is typically the fastest in-memory option, depending on data size, data types, and the value distribution of the join key columns. For each query, ClickHouse decides whether to build a single hash table or to split the hash table into parts that several threads fill concurrently, which the decision tree shows as parallel hash. Theparallel_hash_join_thresholdsetting controls this decision: the hash table is split when the estimated number of rows in the right table reaches the threshold, or when no estimate is available. Since 26.11,parallel_hashis an obsolete alias ofhash, so listing it injoin_algorithmdoes not change this decision. -
(4) If the right table does not fit into memory, hash and parallel hash joins can spill by switching to grace hash when
max_bytes_before_external_joinormax_bytes_ratio_before_external_joinis reached. Full sorting merge and partial merge joins can also use external storage. Which approach is fastest depends on the data volume, data types, and value distribution of the join key columns.
grace_hash_join_initial_buckets setting controls the initial number of buckets and provides a tradeoff between memory use and join speed.
Which one of the three disk based algorithms is the fastest depends on the volume of data, the data types, and the value distribution of the join key columns. It is always best to run some benchmarks with realistic data volumes of your data in order to determine which algorithm is the fastest.
Decision tree examples
The following examples apply each step of the decision tree to the Stack Overflow dataset. To see which algorithm executes a JOIN, run the query withEXPLAIN actions = 1 and read the Algorithm line in the output.
(1) direct. The following dictionary stores the display name of each user, and the query looks up the author of each highly rated post:
Algorithm line reports DirectKeyValueJoin. The dictionary uses the COMPLEX_KEY_HASHED layout to keep the Int32 type of users.Id. A layout with a simple key, such as HASHED, converts the key to UInt64, which cannot be joined with the Int32 column posts.OwnerUserId.
(2) full_sorting_merge. The badges table is sorted by UserId, and the sorting key of the users table starts with Id, so both tables are physically ordered by the JOIN key:
Algorithm line reports FullSortingMergeJoin, and both ReadFromMergeTree steps report the InOrder read type. ClickHouse reads both tables in the order of the JOIN key instead of sorting them.
(3) hash. The default join_algorithm executes the following JOIN with hash:
SETTINGS clause, ClickHouse splits the hash table only when the estimated number of rows in the right-hand table reaches the default parallel_hash_join_threshold of 100,000. With parallel_hash_join_threshold = 0, it splits the hash table regardless of the estimate.
(4) Spilling. The following query allows the hash table to grow to 10 GiB in memory. Above this size, ClickHouse switches the JOIN to grace_hash and writes part of the data to temporary storage:
Optimizing for memory
If you want to optimize a join for the lowest memory usage instead of the fastest execution time, then you can use this decision tree instead: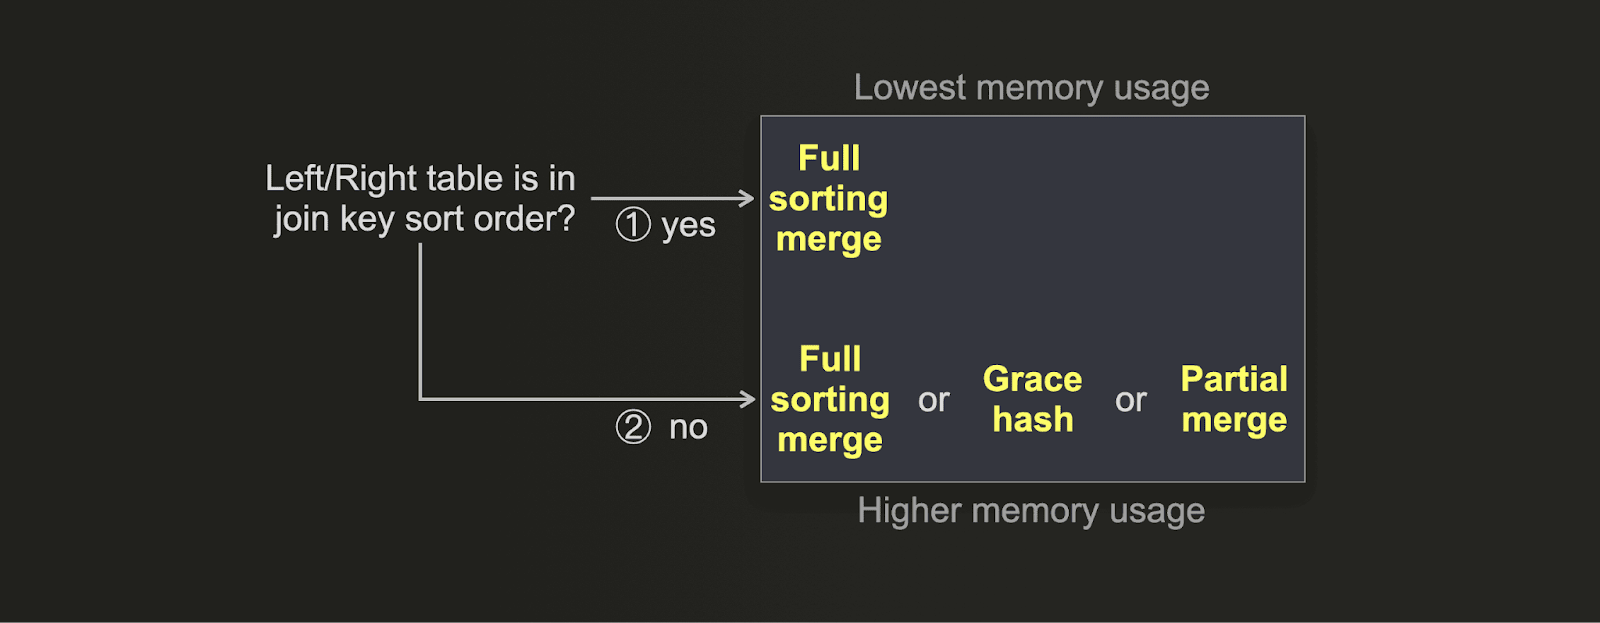
- (1) If your table’s physical row order matches the join key sort order, then the memory usage of the full sorting merge join is as low as it gets with the additional benefit of good join speed because the sorting phase is disabled.
- (2) The
grace_hashalgorithm can be tuned for very low memory usage by increasinggrace_hash_join_initial_bucketsat the expense of JOIN speed. Thepartial_mergealgorithm intentionally uses a low amount of main memory. Thefull_sorting_mergealgorithm with external sorting enabled generally uses more memory thanpartial_mergewhen the row order does not match the key sort order, with the benefit of significantly better JOIN execution time. Thehashalgorithm can also reduce memory pressure by switching tograce_hashat the configured spill threshold.
JOIN optimization examples
The following examples use the Stack Overflow dataset and apply the recommendations progressively. The measurements below are medians from five runs on a ClickHouse Cloud service running ClickHouse 26.8.1 withmax_threads = 4. Each query was warmed once, the query order was alternated, and use_query_cache and use_query_condition_cache were disabled.
Replace ANY INNER JOIN with IN
In this test, the IN query was 2.7 times faster and used 83% less peak memory.
This query counts posts that do not mention ClickHouse but have at least one comment that does:
86 as a result. Its median elapsed time was 27.101 seconds, with 970.01 MiB peak memory. It read 150.20 million rows and 51.77 GiB of data.
The query needs only the existence of a matching comment. An IN subquery avoids producing a JOIN result:
IN query also returns 86. Its median elapsed time was 10.206 seconds, with 162.81 MiB peak memory. It read 174.20 million rows and 19.02 GiB of data.
The two queries return the same result because posts.Id is unique. The rewrite is equivalent only when the left-hand JOIN key is unique, because ANY INNER JOIN returns at most one left-hand row per key, while IN returns every left-hand row that has a match.
Filter both sides before replacing the JOIN
In this test, the rewrite reduced median elapsed time by 18% and peak memory by 14%. This query counts up-votes for Java-related posts created since 2020. The date condition is applied to both inputs before the JOIN:261915 as a result. Its median elapsed time was 0.850 seconds, with 59.96 MiB peak memory. It read 80.94 million rows and 1.13 GiB of data.
Only the existence of a matching post is required for each vote, so the JOIN can then be replaced with IN while retaining filters on both inputs:
IN query also returns 261915. Its median elapsed time was 0.696 seconds, with 51.70 MiB peak memory. It read 46.20 million rows and 817.49 MiB of data.
The rewrite is equivalent because posts.Id is unique, so each vote matches at most one post.