---
title: "ClickHouse Release 25.10"
date: "2025-11-06T09:38:55.639Z"
author: "ClickHouse"
category: "Engineering"
excerpt: "ClickHouse 25.10 is available. In this post, you will learn about join improvements, a new data type for vector search, late materialization of secondary indices, and more!"
---

# ClickHouse Release 25.10

Another month goes by, which means it’s time for another release! 

<p>ClickHouse version 25.10 contains 20 new features &#128123; 30 performance optimizations &#128302; 103 bug fixes &#127875;</p>

This release introduces a collection of join improvements, a new data type for vector search, late materialization of secondary indices, and more!

## New contributors

A special welcome to all the new contributors in 25.10! The growth of ClickHouse's community is humbling, and we are always grateful for the contributions that have made ClickHouse so popular.

Below are the names of the new contributors:

*0xgouda, Ahmed Gouda, Albert Chae, Austin Bonander, ChaiAndCode, David E. Wheeler, DeanNeaht, Dylan, Frank Rosner, GEFFARD Quentin, Giampaolo Capelli, Grant Holly, Guang, Guang Zhao, Isak Ellmer, Jan Rada, Kunal Gupta, Lonny Kapelushnik, Manuel Raimann, Michal Simon, Narasimha Pakeer, Neerav, Raphaël Thériault, Rui Zhang, Sadra Barikbin, copilot-swe-agent[bot], dollaransh17, flozdra, jitendra1411, neeravsalaria, pranav mehta, zlareb1, |2ustam, Андрей Курганский, Артем Юров*

Hint: if you’re curious how we generate this list… [here](https://gist.github.com/gingerwizard/5a9a87a39ba93b422d8640d811e269e9).

<iframe width="768" height="432" src="https://www.youtube.com/embed/cV2hiOCzDG4?si=xT5zGbG3v6cSLUVc" title="YouTube video player" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture; web-share" referrerpolicy="strict-origin-when-cross-origin" allowfullscreen></iframe>

You can also [view the slides from the presentation](https://presentations.clickhouse.com/2025-release-25.10/).

## Lazy columns replication in JOINs

### Contributed by Pavel Kruglov

> "When will you stop optimizing join performance?"  
We will never stop!

This release once again brings JOIN performance optimizations.

The first join improvement in 25.10 is **lazy columns replication**, a new optimization that reduces CPU and memory usage when JOINs produce many duplicate values.

When running JOIN queries (including those using the [arrayJoin](https://clickhouse.com/docs/sql-reference/functions/array-join) function), values from the input tables are often replicated in the result, especially when there are many matches for a given key.

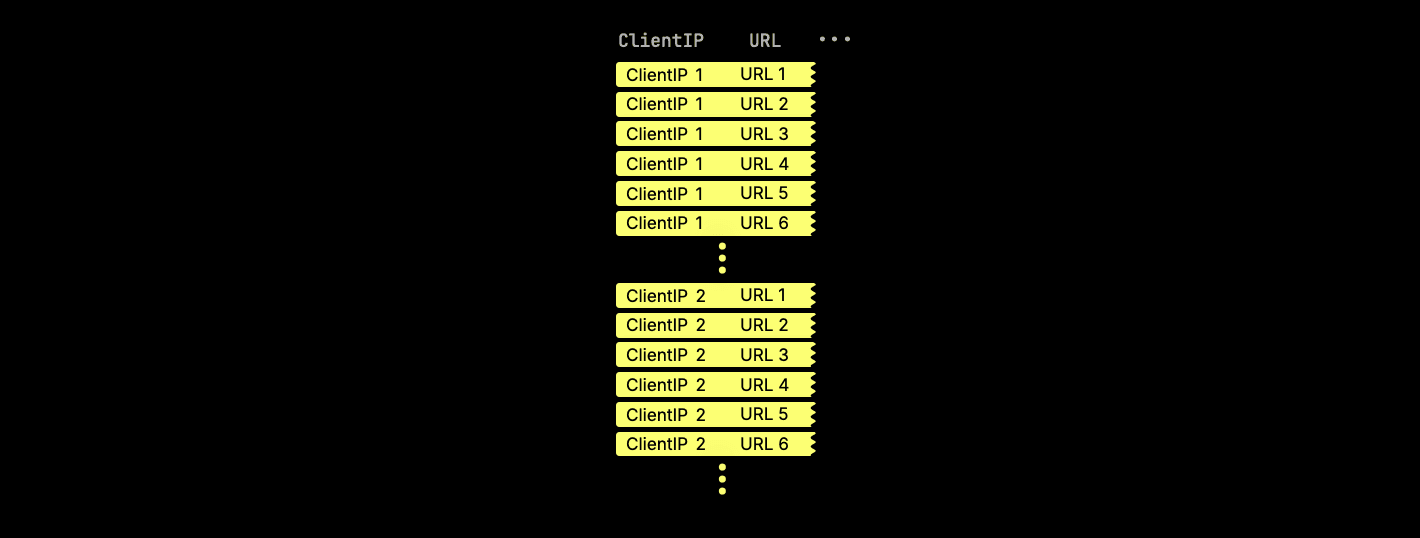
As an example, consider a hits table containing [anonymized web analytics data](https://clickhouse.com/docs/getting-started/example-datasets/metrica), sketched below with two columns, `ClientIP` and `URL`:
![25.10-image1.png](https://clickhouse.com/uploads/25_10_image1_63adbec231.png)

When we run a self-join:

<pre><code type='click-ui' language='sql'>
SELECT ...
FROM
    hits AS t1 INNER JOIN hits AS t2
    ON t1.ClientIP = t2.ClientIP;
</code></pre>

Then the result can heavily duplicate values from both sides:

![25.10-image2.png](https://clickhouse.com/uploads/25_10_image2_cb252579b2.png)


For large columns (like `URL`), this replication consumes significant CPU cycles and memory, as the same values are repeatedly copied in memory.

With **25.10**, ClickHouse no longer spends CPU and memory replicating identical values during JOINs.

Instead, we’ve introduced a **new internal representation** for replicated columns like `URL`.

Rather than physically replicating data, ClickHouse now keeps the **original non-replicated column** alongside a **compact index column** that points to it:

![25.1-image3.png](https://clickhouse.com/uploads/25_1_image3_362ce06d45.png)

We call this mechanism **lazy columns replication**; it defers physical value replication until it’s actually needed (and often, it never is).

To control this behavior, use the settings

* [enable_lazy_columns_replication](https://clickhouse.com/docs/operations/settings/settings#enable_lazy_columns_replication)  
* [allow_special_serialization_kinds_in_output_formats](https://clickhouse.com/docs/operations/settings/settings#allow_special_serialization_kinds_in_output_formats)

### Inspecting the effect in practice

To measure the effect, we benchmarked this feature on an AWS EC2 m6i.8xlarge instance (32 vCPUs, 128 GiB RAM) using the [hits table](https://clickhouse.com/docs/getting-started/example-datasets/metrica). 

*Here is how you can [create](https://github.com/ClickHouse/ClickBench/blob/main/clickhouse-cloud/create.sql) and [load](https://github.com/ClickHouse/ClickBench/blob/54b1b9f0b81093aa74406c3d844c410205b89817/clickhouse-cloud/benchmark.sh#L17) this table on your own.*

First, we ran the example self-join **without lazy replication**:

<pre><code type='click-ui' language='sql'>
SELECT sum(cityHash64(URL))
FROM
    hits AS t1 INNER JOIN hits AS t2
    ON t1.ClientIP = t2.ClientIP
SETTINGS
    enable_lazy_columns_replication = 0,
    allow_special_serialization_kinds_in_output_formats = 0;
</code></pre>

<pre><code type='click-ui' language='text' show_line_numbers='false'>
┌─sum(cityHash64(URL))─┐
│  8580639250520379278 │
└──────────────────────┘

1 row in set. Elapsed: 83.396 sec. Processed 199.99 million rows, 10.64 GB (2.40 million rows/s., 127.57 MB/s.)
Peak memory usage: 4.88 GiB.
</code></pre>

Then, we ran the same query **with lazy columns replication enabled**:

<pre><code type='click-ui' language='sql'>
SELECT sum(cityHash64(URL))
FROM
    hits AS t1 INNER JOIN hits AS t2
    ON t1.ClientIP = t2.ClientIP
SETTINGS
    enable_lazy_columns_replication = 1,
    allow_special_serialization_kinds_in_output_formats = 1;
</code></pre>

<pre><code type='click-ui' language='text' show_line_numbers='false'>
┌─sum(cityHash64(URL))─┐
│  8580639250520379278 │
└──────────────────────┘

1 row in set. Elapsed: 4.078 sec. Processed 199.99 million rows, 10.64 GB (49.04 million rows/s., 2.61 GB/s.)
Peak memory usage: 4.57 GiB.
</code></pre>

**Result:** “Lazy columns replication” made this self-join over **20× faster** while slightly reducing peak memory use, by avoiding unnecessary copying of large string values.

## Bloom filters in JOINs

### Contributed by Alexander Gololobov

The next join optimization generalizes a technique already used in ClickHouse’s [full sorting merge join](https://clickhouse.com/blog/clickhouse-fully-supports-joins-full-sort-partial-merge-part3#full-sorting-merge-join) algorithm, where joined tables can be [filtered by each other’s join keys](https://clickhouse.com/blog/clickhouse-fully-supports-joins-full-sort-partial-merge-part3#filtering-tables-by-each-others-join-key-values-before-joining) before the actual join takes place.

In **25.10**, a similar optimization has been introduced for ClickHouse’s fastest join algorithm, the [parallel hash join](https://clickhouse.com/blog/clickhouse-fully-supports-joins-hash-joins-part2#parallel-hash-join).

The join is sped up by ① building a bloom filter from the join’s right side join key data at runtime and passing this filter to the ② scan in the join’s left side data. The diagram below sketches this for the parallel hash join’s physical query plan (“query pipeline”). *You can read how the rest of this plan works [here](https://clickhouse.com/blog/clickhouse-fully-supports-joins-hash-joins-part2#parallel-hash-join).*

![25.10-image3.png](https://clickhouse.com/uploads/25_10_image3_1ce948e652.png)

This optimization is controlled by the setting [enable_join_runtime_filters](https://clickhouse.com/docs/operations/settings/settings#enable_join_runtime_filters). 

We benchmarked this feature on an AWS EC2 m6i.8xlarge instance (32 vCPUs, 128 GiB RAM) using the [TPC-H dataset](https://clickhouse.com/docs/getting-started/example-datasets/tpch) with scale factor 100. Below, we’ll first inspect how the optimization changes the query plan, and then measure its impact in practice.

### Inspecting the logical plan

The easiest way to look under the hood of a JOIN query is by inspecting its **logical query plan** with `EXPLAIN plan`.

Let’s do that for a simple join between the TPC-H `orders` and `customer` tables on the `custkey` column, where we **disabled** the bloom filter based pre-filtering:

<pre><code type='click-ui' language='sql'>
EXPLAIN plan
SELECT *
FROM orders, customer
WHERE o_custkey = c_custkey
SETTINGS enable_join_runtime_filters = 0;
</code></pre>

The relevant part of the plan looks like this:

<pre><code type='click-ui' language='text' show_line_numbers='false'>
...                             
Join                                                       
...
ReadFromMergeTree (default.orders)                   
ReadFromMergeTree (default.customer) 
</code></pre>

We’ll skip the rest of the plan and focus on the core mechanics.

Reading the output from **bottom to top**, we can see that ClickHouse plans to read the data from the two tables, `orders` and `customer`, and perform the join.

Next, let’s inspect the logical query plan for the same join, but this time **with runtime pre-filtering enabled**:

<pre><code type='click-ui' language='sql'>
EXPLAIN plan
SELECT *
FROM orders, customer
WHERE o_custkey = c_custkey
SETTINGS enable_join_runtime_filters = 1;
</code></pre>

The relevant parts of the plan look like this:

<pre><code type='click-ui' language='text' show_line_numbers='false'>
...
Join                                                                                                                                                                                             
...                                                                                                                                                                         
Prewhere filter column: __filterContains(_runtime_filter_14211390369232515712_0, __table1.o_custkey)                                                                          
...
BuildRuntimeFilter (Build runtime join filter on __table2.c_custkey (_runtime_filter_14211390369232515712_0))
...
</code></pre>

Reading the plan from **bottom to top**, we can see that ClickHouse first ① builds a **Bloom filter** from the join key values on the **right-hand side** (`customer`) table.

This runtime filter is then ② applied as a [**PREWHERE**](https://clickhouse.com/docs/optimize/prewhere) **filter** on the **left-hand side** (`orders`) table, allowing irrelevant rows to be skipped **before** the join is executed.

### Running the query with and without runtime filtering

Now let’s actually run a slightly extended version of that join query, this time joining `orders`, `customer`, and `nation`, and calculating the average order total for customers from France.

We’ll start with **runtime pre-filtering disabled**:

<pre><code type='click-ui' language='sql'>
SELECT avg(o_totalprice)
FROM orders, customer, nation
WHERE (c_custkey = o_custkey) AND (c_nationkey = n_nationkey) AND (n_name = 'FRANCE')
SETTINGS enable_join_runtime_filters = 0;
</code></pre>

<pre><code type='click-ui' language='text' show_line_numbers='false'>
┌──avg(o_totalprice)─┐
│ 151149.41468432106 │
└────────────────────┘

1 row in set. Elapsed: 1.005 sec. Processed 165.00 million rows, 1.92 GB (164.25 million rows/s., 1.91 GB/s.)
Peak memory usage: 1.24 GiB.
</code></pre>

Then, we run the same query again, this time **with runtime pre-filtering enabled**:

<pre><code type='click-ui' language='sql'>
SELECT avg(o_totalprice)
FROM orders, customer, nation
WHERE (c_custkey = o_custkey) AND (c_nationkey = n_nationkey) AND (n_name = 'FRANCE')
SETTINGS enable_join_runtime_filters = 1;
</code></pre>

<pre><code type='click-ui' language='text' show_line_numbers='false'>
┌──avg(o_totalprice)─┐
│ 151149.41468432106 │
└────────────────────┘

1 row in set. Elapsed: 0.471 sec. Processed 165.00 million rows, 1.92 GB (350.64 million rows/s., 4.08 GB/s.)
Peak memory usage: 185.18 MiB.
</code></pre>

**Result:**

With runtime pre-filtering enabled, the same query ran **2.1× faster** while using **nearly 7× less memory**.

By filtering rows early with Bloom filters, ClickHouse avoids scanning and processing unnecessary data, delivering faster joins and lower resource usage.

## Push-down of complex conditions in JOINs

### Contributed by Yarik Briukhovetskyi

ClickHouse can now **push down complex OR conditions** in JOIN queries to filter each table earlier, before the join actually happens.

This optimization works when every branch of an OR condition includes at least one filter (predicate) for each table involved in the join.

For example:

<pre><code type='click-ui' language='sql'>
(t1.k IN (1,2) AND t2.x = 100)
OR
(t1.k IN (3,4) AND t2.x = 200)
</code></pre>

In this case, both sides of the join (t1 and t2) have predicates in every branch.

ClickHouse can therefore **combine and push them down** as:

* `t1.k IN (1,2,3,4)` for the left table

* `t2.x IN (100,200)` for the right table

This allows both tables to be **pre-filtered before the join**, reducing the data read and improving performance.

This optimization is available under the setting [use_join_disjunctions_push_down](https://clickhouse.com/docs/operations/settings/settings#use_join_disjunctions_push_down). 

To see how this optimization works in practice, we’ll look at a simple example using the [**TPC-H dataset**](https://clickhouse.com/docs/getting-started/example-datasets/tpch) (scale factor 100) on an **AWS EC2 m6i.8xlarge instance** (32 vCPUs, 128 GiB RAM).

We’ll join the customer and nation tables on c_nationkey, using a condition that contains two OR branches, each filtering both sides of the join.

### Inspecting the logical plan

First, let’s inspect the **logical query plan** for this query **without** the push-down optimization:

<pre><code type='click-ui' language='sql'>
EXPLAIN plan
SELECT *
FROM customer AS c
INNER JOIN nation AS n
    ON c.c_nationkey = n.n_nationkey
WHERE (c.c_name LIKE 'Customer#00000%' AND n.n_name = 'GERMANY')
   OR (c.c_name LIKE 'Customer#00001%' AND n.n_name = 'FRANCE')
SETTINGS use_join_disjunctions_push_down = 0;
</code></pre>

In this plan, ClickHouse simply reads data from both tables and applies the full filter **during** the join:

<pre><code type='click-ui' language='text' show_line_numbers='false'>
Join                                                       
...
ReadFromMergeTree (default.customer)
ReadFromMergeTree (default.nation)
</code></pre>

Now, let’s enable the new optimization:

<pre><code type='click-ui' language='sql'>
EXPLAIN plan
SELECT *
FROM customer AS c
INNER JOIN nation AS n
    ON c.c_nationkey = n.n_nationkey
WHERE (c.c_name LIKE 'Customer#00000%' AND n.n_name = 'GERMANY')
   OR (c.c_name LIKE 'Customer#00001%' AND n.n_name = 'FRANCE')
SETTINGS use_join_disjunctions_push_down = 1;
</code></pre>

This time, ClickHouse identifies that both branches contain predicates for both tables.

It **derives separate filters** for each side, pushing them down so that both customer and nation are filtered **before** the join:

<pre><code type='click-ui' language='text' show_line_numbers='false'>
Join
...
Filter
ReadFromMergeTree (default.customer)
...
Filter
ReadFromMergeTree (default.nation)
</code></pre>

### Benchmarking the effect

Next, let’s actually run the query with the optimization disabled and enabled to see the performance difference.

**Without push-down:**

<pre><code type='click-ui' language='sql'>
SELECT *
FROM customer AS c
INNER JOIN nation AS n
    ON c.c_nationkey = n.n_nationkey
WHERE (c.c_name LIKE 'Customer#00000%' AND n.n_name = 'GERMANY')
   OR (c.c_name LIKE 'Customer#00001%' AND n.n_name = 'FRANCE')
SETTINGS use_join_disjunctions_push_down = 0;
</code></pre>   

<pre><code type='click-ui' language='text' show_line_numbers='false'>
788 rows in set. Elapsed: 0.240 sec. Processed 15.00 million rows, 2.93 GB (62.56 million rows/s., 12.21 GB/s.)
Peak memory usage: 261.30 MiB.
</code></pre>

**With push-down enabled:**

<pre><code type='click-ui' language='sql'>
SELECT *
FROM customer AS c
INNER JOIN nation AS n
    ON c.c_nationkey = n.n_nationkey
WHERE (c.c_name LIKE 'Customer#00000%' AND n.n_name = 'GERMANY')
   OR (c.c_name LIKE 'Customer#00001%' AND n.n_name = 'FRANCE')
SETTINGS use_join_disjunctions_push_down = 0;
</code></pre>

<pre><code type='click-ui' language='text' show_line_numbers='false'>
788 rows in set. Elapsed: 0.010 sec. Processed 24.60 thousand rows, 4.81 MB (2.47 million rows/s., 482.53 MB/s.)
Peak memory usage: 4.30 MiB.
</code></pre>

**Result:**

With push-down enabled, the same query ran **24× faster** and used **over 60× less memory**.

By pushing filters for both sides of the join down to the table scan, ClickHouse avoids reading and processing millions of irrelevant rows.

## Automatically build column statistics for MergeTree tables

### Contributed by Anton Popov

This is the fourth join-related optimization in this release, albeit an indirect one.

In the previous release, ClickHouse introduced [**automatic global join reordering**](https://clickhouse.com/blog/clickhouse-release-25-09#join-reordering), allowing the engine to efficiently reorder complex join graphs spanning dozens of tables. This resulted in significant improvements, for example, [a **1,450x speedup** and **25× reduction in memory usage**](https://clickhouse.com/blog/clickhouse-release-25-09#benchmarks-tpc-h-results) on one TPC-H example query.

Global join reordering works best when [**column statistics**](https://clickhouse.com/docs/engines/table-engines/mergetree-family/mergetree#available-types-of-column-statistics) are available for the join keys and filters involved. Until now, these statistics had to be created manually for each column.

Starting with **25.10**, ClickHouse can now **automatically create statistics** for all suitable columns in a MergeTree table using the new table-level setting [auto_statistics_types](https://clickhouse.com/docs/operations/settings/merge-tree-settings#auto_statistics_types).

This setting defines which types of statistics to build (for example, `minmax`, `uniq`, `countmin`):

<pre><code type='click-ui' language='sql'>
CREATE TABLE tpch.orders (...) ORDER BY (o_orderkey)
SETTINGS auto_statistics_types = 'minmax, uniq, countmin';
</code></pre>

This enables statistics generation for all columns in the table automatically.

You can also configure it globally for all MergeTree tables in your server configuration:

<pre><code type='click-ui' language='bash'>
$ cat /etc/config.d/merge_tree.yaml
</code></pre>


<pre><code type='click-ui' language='text' show_line_numbers='false'>
merge_tree:
    auto_statistics_types: 'minmax, uniq, countmin'
</code></pre>

By keeping statistics up to date automatically, ClickHouse can make smarter join and filter decisions, improving query planning and reducing both memory use and runtime without manual tuning.

> These four features (**lazy columns replication**, **bloom filters in JOINs**, **push-down of complex conditions**, and **automatic column statistics**) are the latest in a long line of JOIN optimizations in ClickHouse, and they won’t be the last.

## QBit data type

### Contributed by Raufs Dunamalijevs

QBit is a data type for vector embeddings that lets you tune search precision at runtime. It uses a bit-sliced data layout where every number is sliced by bits, and at query time, we specify, how many (most significant) bits to take.

<pre><code type='click-ui' language='sql'>
CREATE TABLE vectors (
    id UInt64, name String, ...
    vec QBit(BFloat16, 1536)
) ORDER BY ();
</code></pre>

<pre><code type='click-ui' language='sql'>
SELECT id, name FROM vectors
ORDER BY L2DistanceTransposed(vector, target, 10)
LIMIT 10;
</code></pre>

Raufs Dunamalijevs has written in detail about the QBit in the blog post ‘[We built a vector search engine that lets you choose precision at query time](https://clickhouse.com/blog/qbit-vector-search)’.

## SQL updates

### Contributed by Nihal Z. Miaji, Surya Kant Ranjan, Simon Michal

The ClickHouse 25.10 release sees several additions to the supported SQL syntax. 

<iframe width="768" height="432" src="https://www.youtube.com/embed/zfLyRys1IEc?si=dLLatcwmN68qdV5T" title="YouTube video player" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture; web-share" referrerpolicy="strict-origin-when-cross-origin" allowfullscreen></iframe>

First up is general support for the `<=>` (IS NOT DISTINCT FROM) operator, which was previously only supported in the `JOIN ON` part of a query. This operator offers equality comparison that treats NULLs as identical. Let’s have a look at how it works:

<pre><code type='click-ui' language='sql'>
SELECT NULL <=> NULL, NULL = NULL;
</code></pre>

```text
┌─isNotDistinc⋯NULL, NULL)─┬─equals(NULL, NULL)─┐
│                        1 │ ᴺᵁᴸᴸ               │
└──────────────────────────┴────────────────────┘
```


Next up, we have [negative limit and offset](https://clickhouse.com/docs/sql-reference/statements/select/limit). This is useful for a query where we want to retrieve the `n` most recent records, but return them in ascending order. Let’s explore this feature using the [UK property prices dataset](https://clickhouse.com/docs/getting-started/example-datasets/uk-price-paid).

Imagine we want to find properties sold for over £10 million since 2024, in descending date order. We could write the following query:

<pre><code type='click-ui' language='sql'>
SELECT date, price, county, district
FROM uk.uk_price_paid
WHERE date >= '2024-01-01' AND price > 10_000_000
ORDER BY date DESC LIMIT 10;
</code></pre>

```text
┌───────date─┬────price─┬─county────────────────────┬─district──────────────────┐
│ 2025-03-13 │ 12000000 │ CHESHIRE WEST AND CHESTER │ CHESHIRE WEST AND CHESTER │
│ 2025-03-06 │ 18375000 │ STOKE-ON-TRENT            │ STOKE-ON-TRENT            │
│ 2025-03-06 │ 10850000 │ HERTFORDSHIRE             │ HERTSMERE                 │
│ 2025-03-04 │ 11000000 │ PORTSMOUTH                │ PORTSMOUTH                │
│ 2025-03-04 │ 18000000 │ GREATER LONDON            │ HAMMERSMITH AND FULHAM    │
│ 2025-03-03 │ 12500000 │ ESSEX                     │ BASILDON                  │
│ 2025-02-20 │ 16830000 │ GREATER LONDON            │ CITY OF WESTMINSTER       │
│ 2025-02-13 │ 13950000 │ GREATER LONDON            │ KENSINGTON AND CHELSEA    │
│ 2025-02-07 │ 81850000 │ ESSEX                     │ EPPING FOREST             │
│ 2025-02-07 │ 24920000 │ GREATER LONDON            │ HARINGEY                  │
└────────────┴──────────┴───────────────────────────┴───────────────────────────┘
```

But let’s say we want to get those same most recent 10 sales, but have them sorted in ascending order by date. This is where negative limit functionality comes in handy. We can adjust the `ORDER BY` and `LIMIT` parts of the query like so:

<pre><code type='click-ui' language='sql'>
SELECT date, price, county, district
FROM uk.uk_price_paid
WHERE date >= '2024-01-01' AND price > 10_000_000
ORDER BY date LIMIT -10;
</code></pre>

And then we’ll see the following results:

```text
┌───────date─┬────price─┬─county────────────────────┬─district──────────────────┐
│ 2025-02-07 │ 29240000 │ GREATER LONDON            │ MERTON                    │
│ 2025-02-07 │ 75960000 │ WARRINGTON                │ WARRINGTON                │
│ 2025-02-13 │ 13950000 │ GREATER LONDON            │ KENSINGTON AND CHELSEA    │
│ 2025-02-20 │ 16830000 │ GREATER LONDON            │ CITY OF WESTMINSTER       │
│ 2025-03-03 │ 12500000 │ ESSEX                     │ BASILDON                  │
│ 2025-03-04 │ 11000000 │ PORTSMOUTH                │ PORTSMOUTH                │
│ 2025-03-04 │ 18000000 │ GREATER LONDON            │ HAMMERSMITH AND FULHAM    │
│ 2025-03-06 │ 18375000 │ STOKE-ON-TRENT            │ STOKE-ON-TRENT            │
│ 2025-03-06 │ 10850000 │ HERTFORDSHIRE             │ HERTSMERE                 │
│ 2025-03-13 │ 12000000 │ CHESHIRE WEST AND CHESTER │ CHESHIRE WEST AND CHESTER │
└────────────┴──────────┴───────────────────────────┴───────────────────────────┘
```

We can also provide a negative offset alongside a negative limit to paginate through results. To see the next 10 most recent sales sorted in ascending order by date, we can write the following query:

<pre><code type='click-ui' language='sql'>
SELECT date, price, county, district
FROM uk.uk_price_paid
WHERE date >= '2024-01-01' AND price > 10_000_000
ORDER BY date LIMIT -10 OFFSET -10;
</code></pre>

```text
┌───────date─┬─────price─┬─county──────────┬─district────────────┐
│ 2025-01-21 │  10650000 │ NOTTINGHAMSHIRE │ ASHFIELD            │
│ 2025-01-21 │  22722671 │ GREATER LONDON  │ CITY OF WESTMINSTER │
│ 2025-01-22 │ 109500000 │ GREATER LONDON  │ CITY OF LONDON      │
│ 2025-01-24 │  11700000 │ THURROCK        │ THURROCK            │
│ 2025-01-25 │  75570000 │ GREATER LONDON  │ CITY OF WESTMINSTER │
│ 2025-01-29 │  12579711 │ SUFFOLK         │ MID SUFFOLK         │
│ 2025-01-31 │  29307333 │ GREATER LONDON  │ EALING              │
│ 2025-02-07 │  81850000 │ ESSEX           │ EPPING FOREST       │
│ 2025-02-07 │  24920000 │ GREATER LONDON  │ HARINGEY            │
│ 2025-02-07 │ 151420000 │ GREATER LONDON  │ MERTON              │
└────────────┴───────────┴─────────────────┴─────────────────────┘
```

And if we wanted to get the next 10, we’d change the last line of the query to say `LIMIT -10 OFFSET -20`, and so on.

Finally, ClickHouse now supports [`LIMIT BY ALL`](https://clickhouse.com/docs/sql-reference/statements/select/limit-by#limit-by-all). Let’s have a look at an example where we can use this clause. The following query returns information about residential properties sold for more than £10 million in Greater London:

<pre><code type='click-ui' language='sql'>
SELECT town, district, type
FROM uk.uk_price_paid
WHERE county = 'GREATER LONDON' AND price > 10_000_000 AND type <> 'other'
ORDER BY price DESC
LIMIT 10;
</code></pre>

```text
┌─town───┬─district───────────────┬─type─────┐
│ LONDON │ CITY OF WESTMINSTER    │ flat     │
│ LONDON │ CITY OF WESTMINSTER    │ terraced │
│ LONDON │ CITY OF WESTMINSTER    │ flat     │
│ LONDON │ KENSINGTON AND CHELSEA │ terraced │
│ LONDON │ CITY OF WESTMINSTER    │ terraced │
│ LONDON │ KENSINGTON AND CHELSEA │ flat     │
└────────┴────────────────────────┴──────────┘
```

The City of Westminster has been returned many times, which makes sense, as it’s a costly part of the city. Let’s say we only want to return each combination of `(town,district,type)` once. We could do this using the `LIMIT BY` syntax:

<pre><code type='click-ui' language='sql'>
SELECT town, district, type
FROM uk.uk_price_paid
WHERE county = 'GREATER LONDON' AND price > 10_000_000 AND type <> 'other'
ORDER BY price DESC
LIMIT 1 BY town, district, type
LIMIT 10;
</code></pre>

```text
┌─town───┬─district───────────────┬─type──────────┐
│ LONDON │ CITY OF WESTMINSTER    │ flat          │
│ LONDON │ CITY OF WESTMINSTER    │ terraced      │
│ LONDON │ KENSINGTON AND CHELSEA │ terraced      │
│ LONDON │ KENSINGTON AND CHELSEA │ flat          │
│ LONDON │ KENSINGTON AND CHELSEA │ detached      │
│ LONDON │ SOUTHWARK              │ flat          │
│ LONDON │ KENSINGTON AND CHELSEA │ semi-detached │
│ LONDON │ CITY OF WESTMINSTER    │ detached      │
│ LONDON │ CAMDEN                 │ detached      │
│ LONDON │ CITY OF LONDON         │ detached      │
└────────┴────────────────────────┴───────────────┘
```

Alternatively, instead of having to list all field names after the `LIMIT BY`, we use `LIMIT BY ALL`:

<pre><code type='click-ui' language='sql'>
SELECT town, district, type
FROM uk.uk_price_paid
WHERE county = 'GREATER LONDON' AND price > 10_000_000 AND type <> 'other'
ORDER BY price DESC
LIMIT 1 BY ALL
LIMIT 10;
</code></pre>

And we’ll get back the same set of records.

## Arrow Flight server and client compatibility

### Contributed by zakr600, Vitaly Baranov

In ClickHouse 25.8, we introduced the [Arrow Flight integration](https://clickhouse.com/blog/clickhouse-release-25-08#arrow-flight-integration), which made it possible to use ClickHouse as an Arrow Flight server or client. 

The integration was initially quite rudimentary, but it has been developed over the last couple of months. As of ClickHouse 25.10, we can query the ClickHouse Arrow Flight server using the ClickHouse Arrow Flight client.

We can add a config file containing the following to our ClickHouse Server:

<pre><code type='click-ui' language='yaml'>
arrowflight_port: 6379
arrowflight:
  enable_ssl: false
  auth_required: false
</code></pre>

We’ll then have an Arrow Flight Server running on port 6379. At the moment, you can only query the default database, but we can use the new [alias table engine](https://clickhouse.com/docs/engines/table-engines/special/alias) to work around this:

<pre><code type='click-ui' language='sql'>
CREATE TABLE uk_price_paid
ENGINE = Alias(uk, uk_price_paid);
</code></pre>

And then we can query that table using our Arrow client:

<pre><code type='click-ui' language='sql'>
SELECT max(price), count()
FROM arrowflight('localhost:6379', 'uk_price_paid', 'default', '');
</code></pre>

```text
┌─max(price)─┬──count()─┐
│  900000000 │ 30452463 │
└────────────┴──────────┘
```

## Late materialization of secondary indices

### Contributed by George Larionov

The 25.10 release also introduces settings that allow us to delay the materialization of secondary indices. We might want to do this if we have tables that contain indices that take a while to populate (e.g., the [approximate vector search index](https://clickhouse.com/docs/engines/table-engines/mergetree-family/annindexes)).

Let’s see how this works with help from some DBpedia embeddings. We’ll ingest them into the following table:

<pre><code type='click-ui' language='sql'>
CREATE OR REPLACE TABLE dbpedia
(
  id      String,
  title   String,
  text    String,
  vector  Array(Float32) CODEC(NONE),
  INDEX vector_idx vector TYPE vector_similarity('hnsw', 'L2Distance', 1536)
) ENGINE = MergeTree
ORDER BY (id);
</code></pre>

We’ll then download one Parquet file that contains around 40,000 embeddings:

<pre><code type='click-ui' language='bash'>
wget https://huggingface.co/api/datasets/Qdrant/dbpedia-entities-openai3-text-embedding-3-large-1536-1M/parquet/default/train/0.parquet
</code></pre>

Now let’s insert those records into our table:

<pre><code type='click-ui' language='sql'>
INSERT INTO dbpedia
SELECT `_id` AS id, title, text, 
       `text-embedding-3-large-1536-embedding` AS vector
FROM file('0.parquet');
</code></pre>

```text
0 rows in set. Elapsed: 6.161 sec. Processed 38.46 thousand rows, 367.26 MB (6.24 thousand rows/s., 59.61 MB/s.)
Peak memory usage: 932.41 MiB.
```

It takes just over 6 seconds to ingest the records, while also materializing the HNSW index. 

Let’s now create a copy of the `dbpedia` table:

<pre><code type='click-ui' language='sql'>
create table dbpedia2 as dbpedia;
</code></pre>

We can now choose to delay the point at which index materialization happens by configuring the following setting:

<pre><code type='click-ui' language='sql'>
SET exclude_materialize_skip_indexes_on_insert='vector_idx';
</code></pre>

If we repeat our earlier insert statement, but on `dbpedia2`:

<pre><code type='click-ui' language='sql'>
INSERT INTO dbpedia2
SELECT `_id` AS id, title, text, 
       `text-embedding-3-large-1536-embedding` AS vector
FROM file('0.parquet');
</code></pre>

We can see it’s significantly quicker:

```text
0 rows in set. Elapsed: 0.522 sec. Processed 38.46 thousand rows, 367.26 MB (73.68 thousand rows/s., 703.59 MB/s.)
Peak memory usage: 931.08 MiB.
```

We can see whether the index has been materialized by writing the following query:

<pre><code type='click-ui' language='sql'>
SELECT table, data_compressed_bytes, data_uncompressed_bytes, marks_bytes FROM system.data_skipping_indices
WHERE name = 'vector_idx';
</code></pre>

```text
┌─table────┬─data_compressed_bytes─┬─data_uncompressed_bytes─┬─marks_bytes─┐
│ dbpedia  │             124229003 │               128770836 │          50 │
│ dbpedia2 │                     0 │                       0 │           0 │
└──────────┴───────────────────────┴─────────────────────────┴─────────────┘
```

In `dbpedia2`, we can see that the number of bytes taken is 0, which is what we’d expect. The index will be materialized in the background merge process, but if we want to make it happen immediately, we can run this query:

<pre><code type='click-ui' language='sql'>
ALTER TABLE dbpedia2 MATERIALIZE INDEX vector_idx 
SETTINGS mutations_sync = 2;
</code></pre>

Re-running the query against the `data_skipping_indices` table will return the following output:

```text
┌─table────┬─data_compressed_bytes─┬─data_uncompressed_bytes─┬─marks_bytes─┐
│ dbpedia  │             124229003 │               128770836 │          50 │
│ dbpedia2 │             124237137 │               128769912 │          50 │
└──────────┴───────────────────────┴─────────────────────────┴─────────────┘
```

Alternatively, we can query the `system.parts` table if we want to see whether any indices have been materialized for a given part:

<pre><code type='click-ui' language='sql'>
SELECT name, table, secondary_indices_compressed_bytes, secondary_indices_uncompressed_bytes, secondary_indices_marks_bytes 
FROM system.parts;
</code></pre>

```text
Row 1:
──────
name:                                 all_1_1_0
table:                                dbpedia
secondary_indices_compressed_bytes:   124229003 -- 124.23 million
secondary_indices_uncompressed_bytes: 128770836 -- 128.77 million
secondary_indices_marks_bytes:        50

Row 2:
──────
name:                                 all_1_1_0_2
table:                                dbpedia2
secondary_indices_compressed_bytes:   124237137 -- 124.24 million
secondary_indices_uncompressed_bytes: 128769912 -- 128.77 million
secondary_indices_marks_bytes:        50
```

We can even disable building indices during merges by using the following setting:

<pre><code type='click-ui' language='sql'>
CREATE TABLE t (...)
SETTINGS materialize_skip_indexes_on_merge = false;
</code></pre>

Or exclude certain (heavy) indices from calculation:

<pre><code type='click-ui' language='sql'>
CREATE TABLE t (...)
SETTINGS exclude_materialize_skip_indexes_on_merge = 'vector_idx';
</code></pre>
